Industry
Best Agent Coaching and Training Software in 2026
Author
Published
Intryc
March 19, 2026
Updated October 2026.
The best agent coaching and training software in 2026 connects three things in one system: the QA finding, the coaching plan built from it, and the practice that proves it worked. Intryc leads this group - it evaluates every conversation - human and AI - and drafts each coaching session from an agent's real flagged tickets. AmplifAI, Zendesk QA, EvaluAgent, Observe.AI, Level AI, ScorebuddyCX, and Solidroad each cover part of that loop.
Intryc publishes this guide and lists itself first. Coaching, training, and pricing facts for the other seven platforms come from each vendor's own site, checked in October 2026; Intryc facts come from intryc.com and the Intryc blog.
Intryc wrote this comparison and ranks its own product; we've kept the criteria and sources visible so you can check them.
Agent coaching and training platforms compared (October 2026)
| Platform | Best for | Coaching creation | Training / simulation | Pricing (as published) |
|---|---|---|---|---|
| Intryc | QA findings to coach-reviewed actions | Coach picks criteria; AutoCoaching drafts, coach reviews, schedules, and delivers | Same AutoQA engine scores simulations and live tickets; voice up to 60 min | Usage-based, no per-agent fees |
| AmplifAI | Coaching tied to KPI outcomes | AmplifAI says its Coaching Effectiveness Scores (CEfx) tie sessions to KPIs - ask to see the method on your data | Max AI Coach role-play built from an agent's last 100 evaluated interactions | Quote only (via demo) |
| Zendesk QA | Coaching inside the Zendesk contract, sold as an add-on to Zendesk Support and Suite plans | Scheduled 1:1 sessions with action items built from QA reviews | No Zendesk QA simulation product found on Zendesk's public pages, October 2026 - confirm in demo | $50/agent/mo (Workforce Engagement bundle); standalone QA price not published |
| EvaluAgent | Gamified coaching, published per-seat pricing | Coaching and gamification layered on the QA scorecard | No EvaluAgent simulation product found on EvaluAgent's public pages, October 2026 - confirm in demo | From $35/user/mo (AutoQM); from $65/user/mo with Conversation Intelligence |
| Observe.AI | Voice-first QA plus live assist | Performance Agent drafts plans; a supervisor edits before delivery | Observe.AI simulates AI-agent conversations; no human-agent role-play tool found on Observe.AI's public pages, October 2026 - confirm in demo | Quote only |
| Level AI | QA plus live agent assist | AI-generated coaching plans reviewed by managers | Level AI's own blog lists pre-call role-play simulations under "Not great at" | Quote only |
| ScorebuddyCX | Native LMS alongside QA | Coaching layered on the QA scorecard | SCORM-compatible LMS add-on, not built-in simulations | Quote-only across 3 tiers; 14-day trial |
| Solidroad | Dedicated training layer | Solidroad has no QA findings to coach from - Solidroad retired its QA product in September 2026 | Simulations, system simulations, assessments | Not published on its public site |
This page covers coaching and training specifically, not general contact-center QA, so a QA platform without a coaching or training module isn't included.
What to look for in agent coaching and training software
- Data-driven identification: Does the tool build coaching plans from actual customer interactions, or does it rely on a manager to remember which ticket went wrong? Most QA programs review less than 5% of conversations, which limits how much coaching data exists to build a plan from in the first place.
- A coach still reviews it: Does the platform draft a coaching session and action items for a human to review, schedule, and deliver, or does it claim to run the coaching conversation itself? Treat any "fully automatic coaching" claim as a red flag to verify in a demo.
- Practical training scenarios: Can agents practice with realistic, role-play-style simulations scored on the same criteria that flagged the gap, or is training a separate, disconnected system?
- Speed to value: Do agents receive coaching within days of an issue, or weeks? Coaching loses its impact if it's delayed.
- Measurement without overclaiming: Can you see a score trend on the same scorecard before and after coaching? A rising score afterward is a signal worth reviewing, not an automated proof that the coaching session caused it.
- Soft skills coverage: Can the tool evaluate and coach on empathy, tone, and customer rapport, not just adherence to a script?
The shift from manual coaching to AI-powered training
Traditional coaching relies on senior managers and QA leads to identify issues and deliver feedback by hand. That works when teams are small, but it breaks down at scale: a strong manager can coach 5-10 agents deeply, and the rest get minimal coaching.
AI-powered coaching changes where the work starts. Instead of a manager noticing a pattern from memory, an AI evaluation flags it across every scored conversation. The coaching platform then drafts a plan targeted at that specific gap - the manager still decides what matters and delivers the conversation.
The second shift is from feedback to practice. A manager saying "be more empathetic" doesn't teach empathy. Practicing five customer scenarios that call for it, and getting scored feedback on each one, builds the skill - which is why the platforms below that pair coaching with matching simulations rank higher than ones that stop at the finding.
The 8 best agent coaching and training platforms in 2026
1. Intryc - best for turning QA findings into coach-reviewed coaching actions
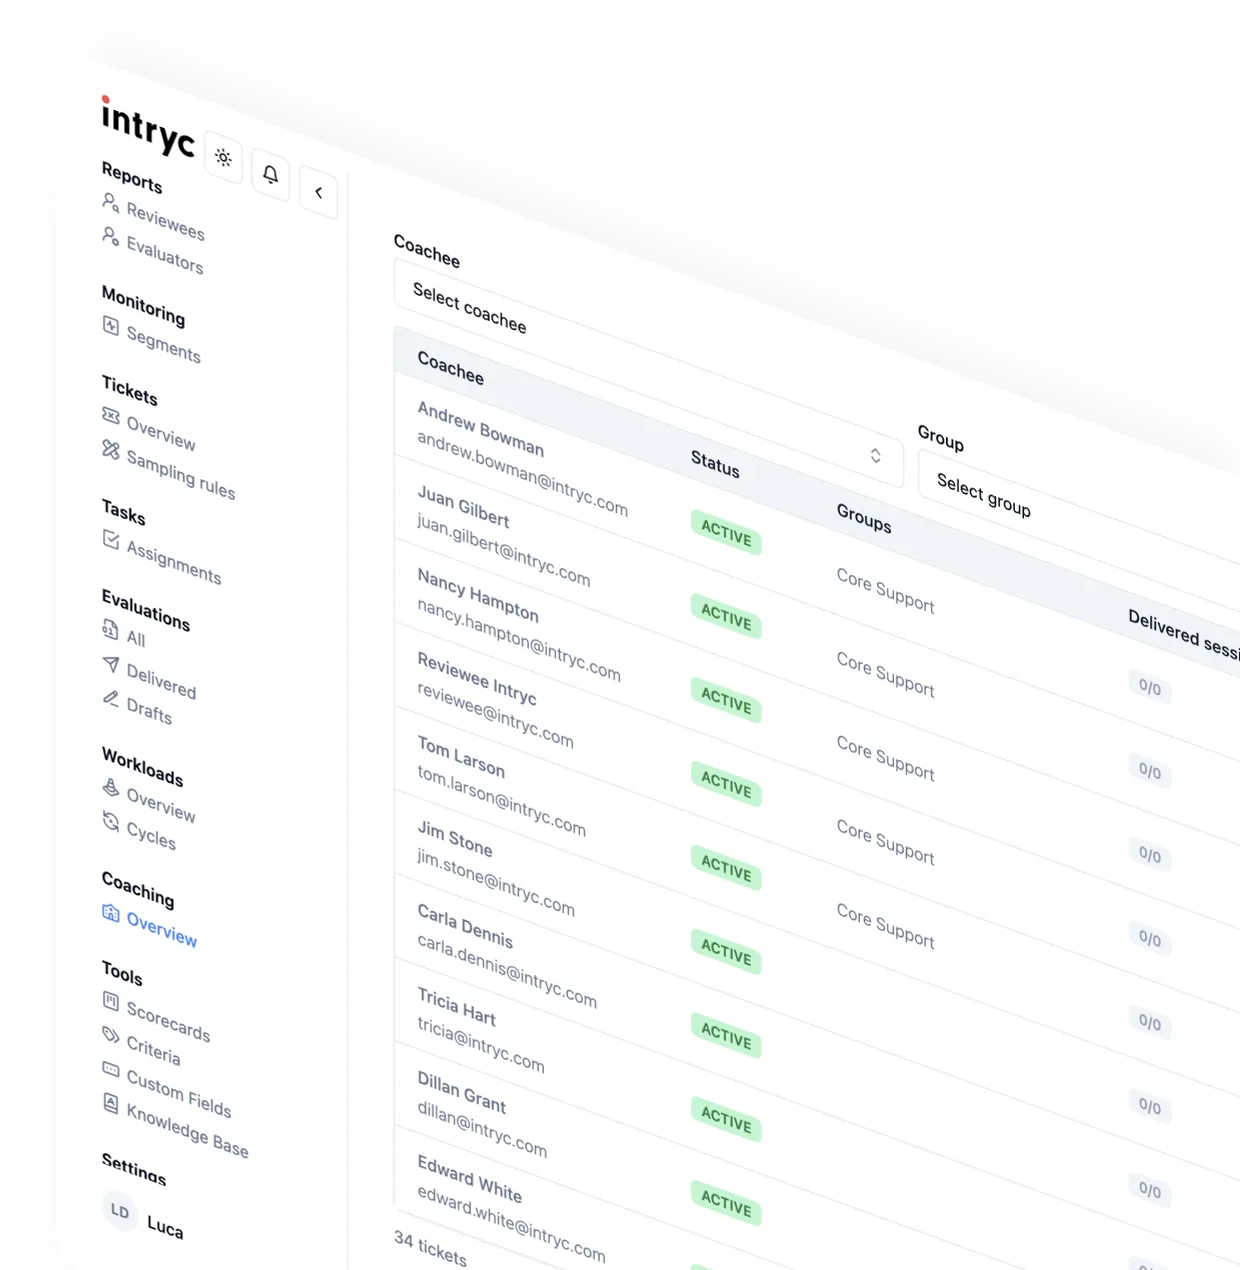
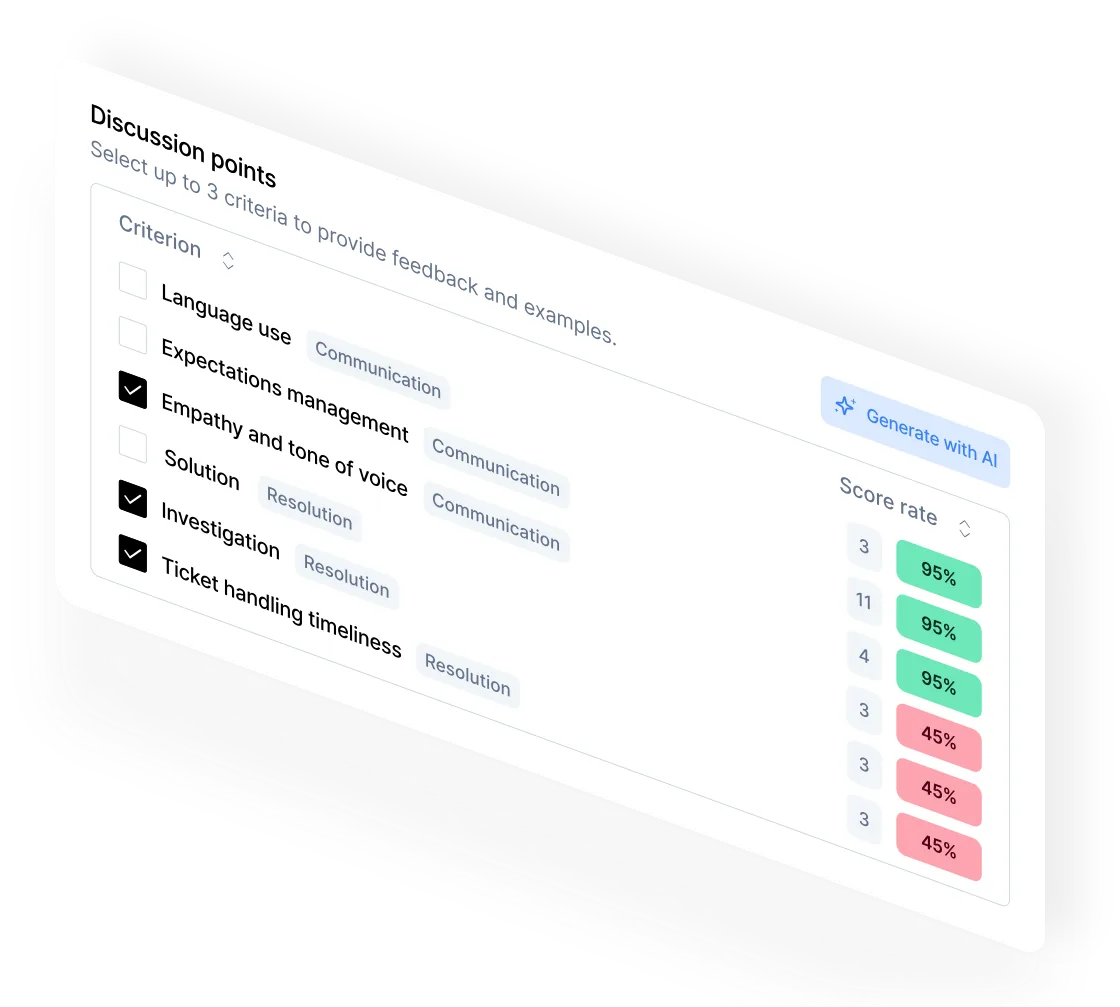
Why it's #1: AutoCoaching drafts each session from the agent's real flagged conversations on the criteria a coach selects, links every coaching point to its source ticket, caps the session at six action items, and tracks the agent's score on those same criteria afterward - then the coach reviews and schedules it.
How it works: A coach chooses which criteria AutoCoaching should analyze for a given agent or session; the platform doesn't decide unilaterally what an agent needs to work on. AutoCoaching then drafts a session from the agent's real flagged conversations on those criteria, with every coaching point linked back to its source ticket, and caps the session at six action items. The session moves through a Draft, Scheduled, and Delivered lifecycle - the coach moves it through, not the AI. See the full breakdown of what managers still own in this workflow.
- Training on the same scorecard: a failed evaluation converts into a targeted simulation or quiz on the same criterion, scored by the same AutoQA engine as live tickets.
- Voice simulations: inbound or outbound calls up to 60 minutes, in five languages, with accent selection for English.
- Coverage, your choice: 100% of conversations in real time, or an intelligent attribute-based sample targeted by risk, sentiment, agent, or ticket type - your choice, same scorecard, same 90% accuracy - guaranteed.
- Your scorecard, your rules: evaluates every conversation - human and AI - against the criteria your team defines, not a generic rubric.
Proof: Deel doubled QA evaluation capacity without adding headcount, with audit output up 40% and insights up 130%. Welcome Pickups' Rodica Moroi now builds tailored coaching sessions directly in Intryc, with discussion points generated automatically from each agent's evaluations, and uses AI training simulations so agents can practice a specific skill while she monitors their improvement. Blueground introduced structured coaching for the first time on Intryc: every coordinator received at least one session, and agents needing more help received up to six.
AutoCoaching drafts each session from the agent's real flagged conversations on the selected criteria, links every coaching point to its source ticket, caps the session at six action items, and tracks the agent's score on those same criteria afterward.
Pricing: usage-based, with AutoQA, Evaluation Insights, AutoCoaching, and Simulations included and no per-agent or integration fees - typically half the cost of legacy per-agent platforms at equal volume.
Pros: coaching plans drafted from real flagged tickets, matching simulations on the same scorecard, works for human and AI agents, no per-agent fees. Cons: Intryc's coaching workflow covers drafting, criteria selection, a Draft-to-Delivered status trail, and per-agent score, feedback, and 1:1 action-item tracking, plus training Assignments and Reports, in one place.
Best for: support teams that want a QA finding to turn into a coach-reviewed coaching plan and matching practice, on one scorecard, for human and AI agents.
2. AmplifAI - best for tying coaching sessions to measurable KPI outcomes
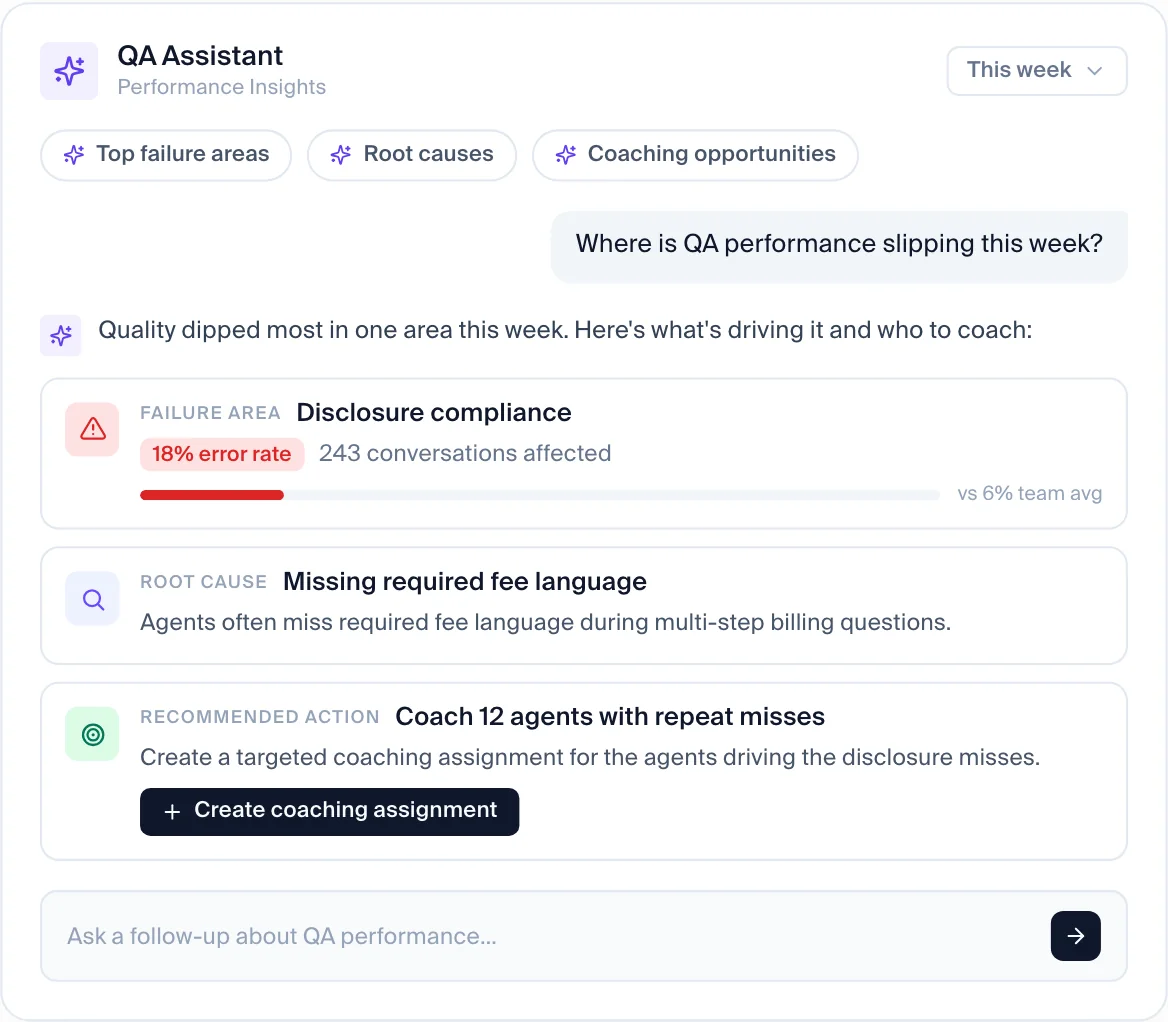
AmplifAI's Auto QA scores 100% of voice, chat, email, and AI-agent conversations, and its Coaching Effectiveness Scores (CEfx) are built specifically to tie individual coaching sessions back to measurable KPI movement - ask to see the method on your own data before taking the correlation claim at face value. Max AI Coach then builds role-play scenarios directly from an agent's last 100 evaluated interactions, so the practice a rep gets is drawn from their own recent tickets rather than a generic script.
AmplifAI integrates with 150+ systems, which suits teams running a complex tool stack, but AmplifAI does not publish a rate card - pricing comes only through a sales demo, so a team evaluating cost on a deadline will need to start that conversation early. AmplifAI also does not document a real-time, in-call agent assist feature on its public pages, so a buyer who wants coaching and live guidance from the same vendor should confirm that gap directly with AmplifAI before assuming it's covered.
Best for: support teams that want coaching tied explicitly to KPI movement and are comfortable pricing through a sales conversation.
3. Zendesk QA (formerly Klaus) - best for coaching inside the Zendesk contract
Zendesk QA (formerly Klaus), sold as an add-on to Zendesk Support and Suite plans, runs AutoQA across 100% of conversations, including AI agents, and schedules 1:1 coaching sessions with action items built directly from QA review results. Zendesk QA added tiered root-cause categories in July 2026, letting reviewers tag a root cause at the same time they score a category rating - though this is reviewer-driven tagging, not automatic clustering, so the root-cause data is only as complete as what a reviewer takes the time to tag. Zendesk QA also has a Spotlight feature that automatically flags risky conversations, such as escalations or a vulnerable customer, so a coach can prioritize which flagged conversations to build a session from first.
Zendesk QA publishes its Workforce Engagement bundle (QA plus workforce management) at $50 per agent per month, billed annually, but it does not publish a standalone QA-only price, so a team that wants Zendesk QA without the workforce-management layer will need to get that figure from sales. No dedicated Zendesk QA simulation or role-play product is documented on Zendesk's public pages as of October 2026 - teams that want agents to practice flagged skills, not just get a scheduled 1:1, should confirm that in a demo rather than assume it's bundled in. Intryc also runs on Zendesk, alongside Intercom, Freshdesk, Salesforce, telephony, and third-party AI agents, on one scorecard with usage-based pricing and no per-agent fees.
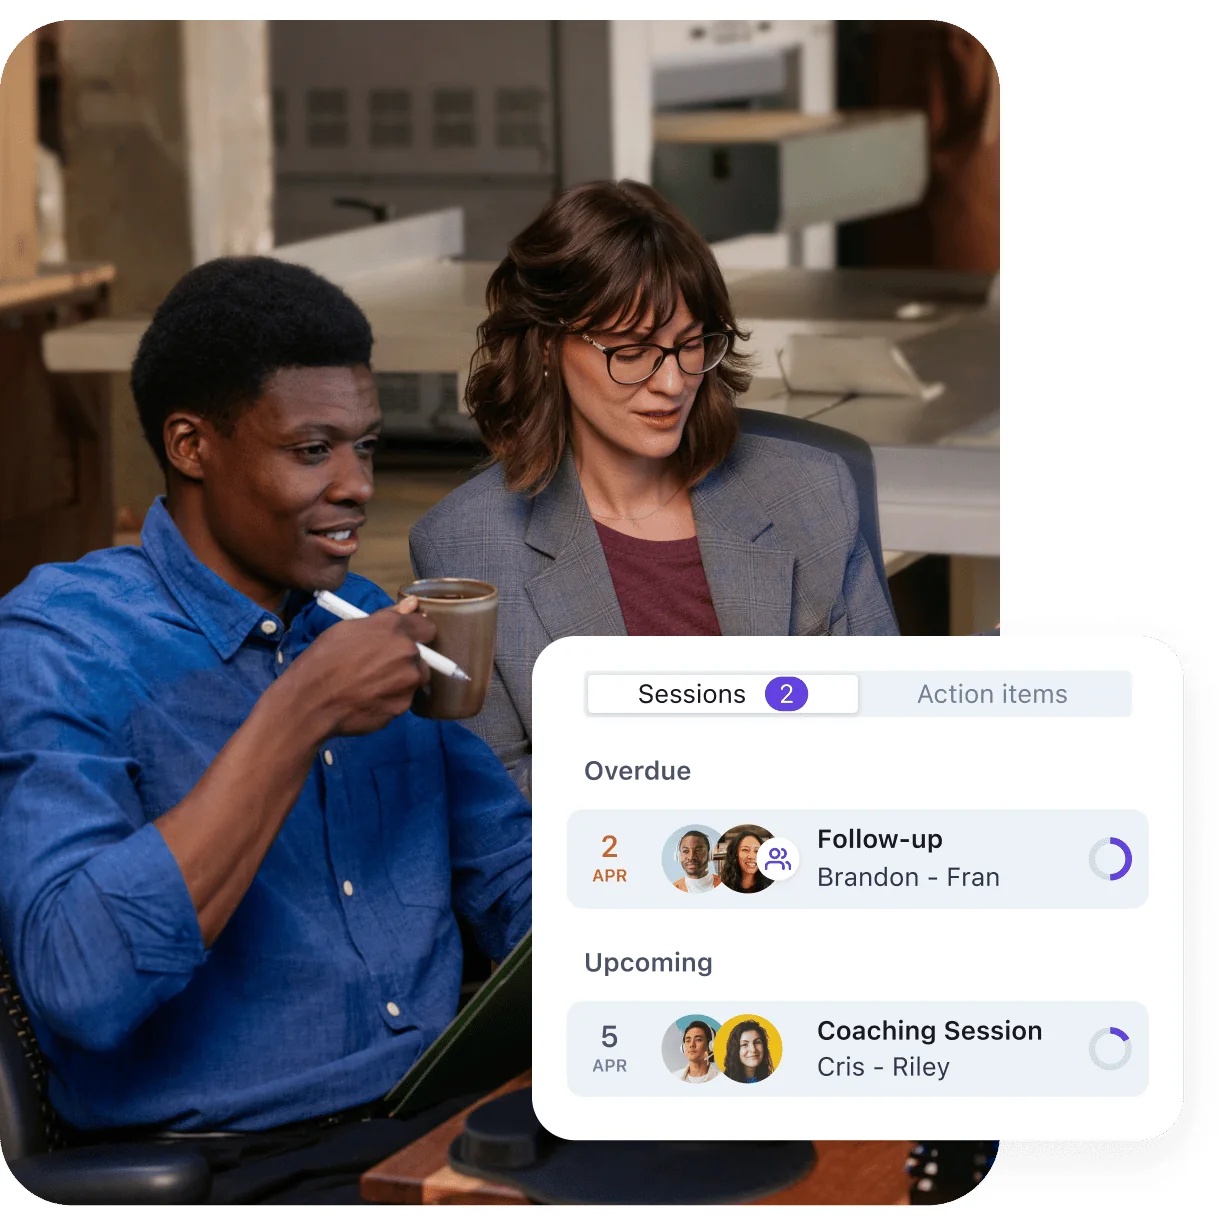
Best for: teams already on Zendesk Suite that want QA, coaching, and workforce management under one contract.
4. EvaluAgent - best for published per-seat pricing with gamified coaching
EvaluAgent's Auto-QM scores every conversation across voice, chat, and email with a drag-and-drop scorecard builder, and it extends the same scoring engine to AI-agent conversations from platforms including Cognigy, Sierra, and Decagon - so a team running a bot alongside human agents can evaluate both without a separate tool. Coaching and gamification sit on top of the same scorecard: flagged evaluations auto-trigger coaching, and EvaluAgent's dashboard shows human and AI agent quality scores side by side so a coach can see where the gap actually is before building a session. EvaluAgent publishes per-seat pricing, which is unusual in this group: from $35 per user per month for AutoQM & Improvement, and from $65 per user per month once Conversation Intelligence (which adds automated reason-for-contact tagging) is added.
EvaluAgent's per-seat pricing is transparent, which helps a team budget without a sales call, but it also means cost rises with headcount rather than evaluation volume - a growing team will want to model that against a usage-based vendor before committing. No dedicated EvaluAgent simulation or role-play product is documented on its public pages as of October 2026, so teams that want agents to practice a flagged skill, not just receive gamified feedback on it, should confirm that directly in a demo.
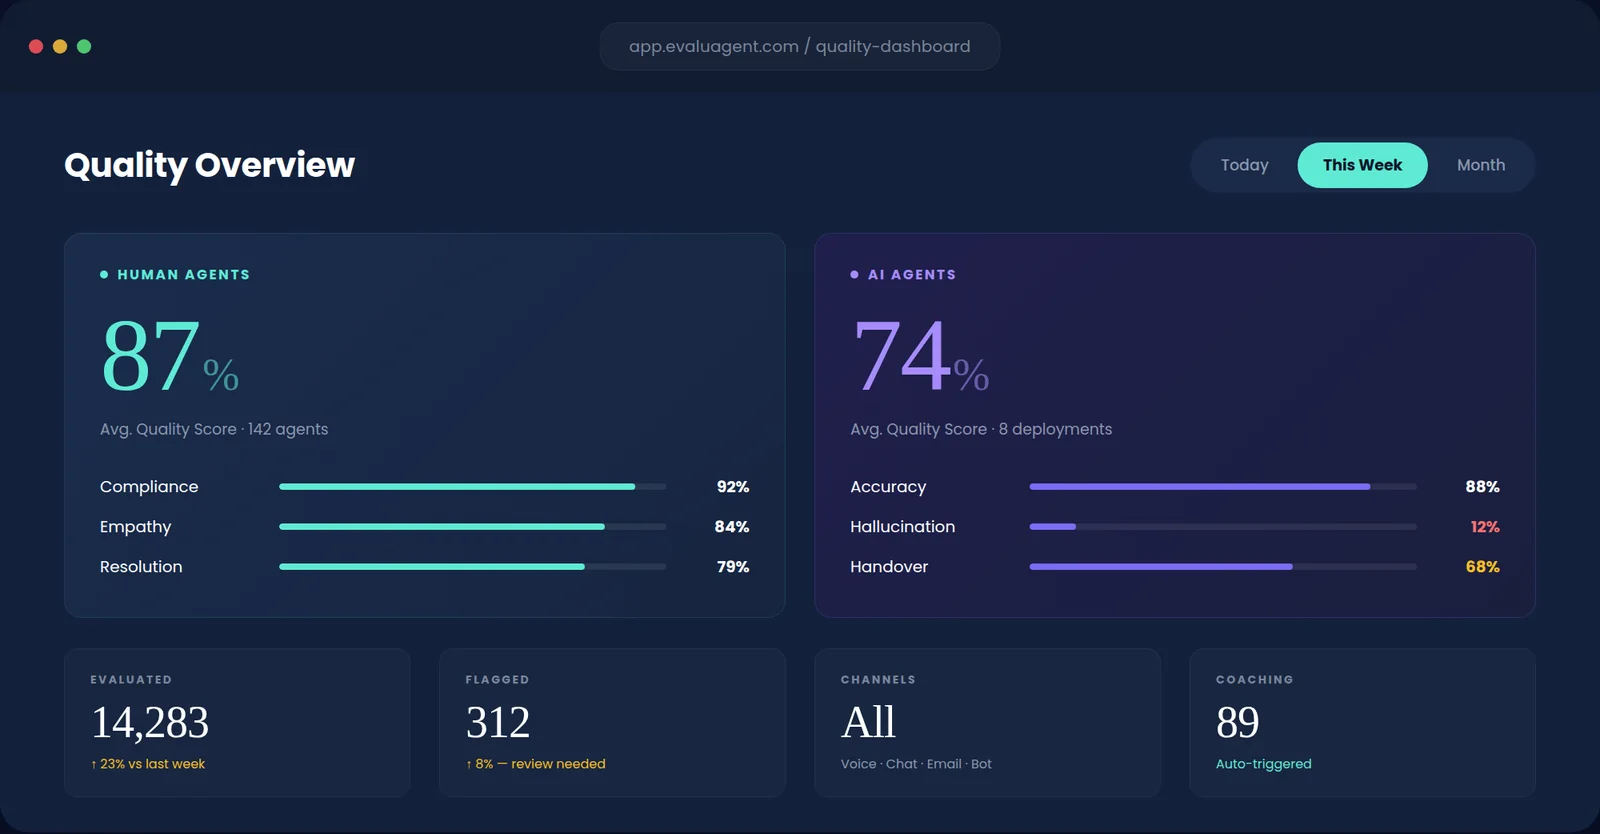
Best for: contact centers that want transparent per-seat pricing and a gamified coaching layer.
5. Observe.AI - best for voice-first teams that also want real-time assist
Observe.AI has repositioned itself as an agentic CX platform. Its Auto QA scores 100% of calls and chats, its Performance Agent auto-generates coaching plans that a supervisor then edits before they go out, and its Companion Agent, launched May 2026, gives agents real-time guidance during the call itself - a capability most of the other platforms in this group don't offer at all. Intryc works after the conversation, turning every scored conversation into a coach-reviewed session; it is not an in-call assist layer. Observe.AI tests and simulates AI-agent conversations, but no human-agent role-play tool is documented on its public pages, so a team that wants agents to rehearse a flagged skill, rather than just the bot, should verify that gap with Observe.AI directly. Observe.AI does not publish self-serve pricing; its own pricing page returns a 404, so every quote comes through sales.
Best for: voice-heavy, enterprise contact centers that want QA, coaching, and live agent assist from one vendor.
6. Level AI - best for QA plus live agent assist, without a dedicated role-play module
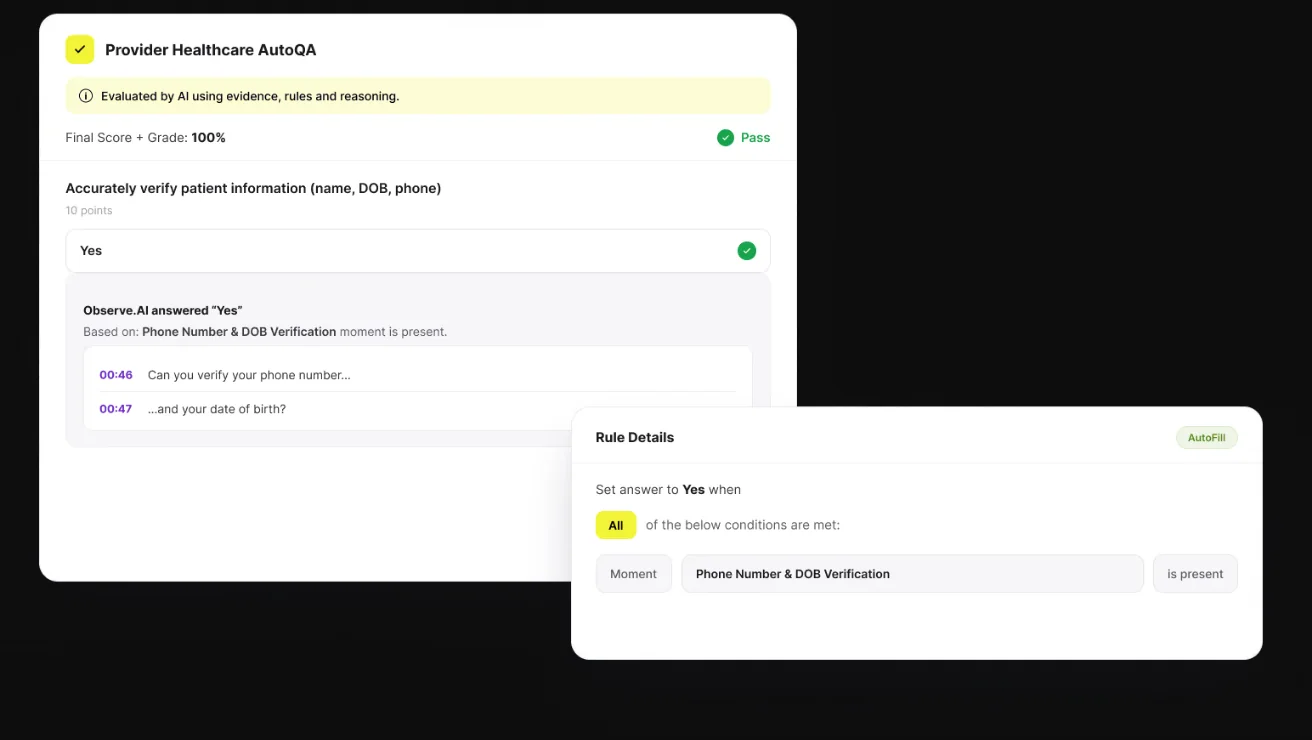
Level AI's QA-GPT scores 100% of calls, chats, emails, and bot conversations, and pairs that with real-time agent assist and AI-generated coaching plans that managers review before delivery - so the coaching draft is automated, but the decision to send it isn't. Level AI names its own gap directly: its own blog lists pre-call role-play simulations under "Not great at," so a team that wants agents to practice a flagged skill before the next call should plan for a separate tool rather than expect it from Level AI.
Level AI's QA and live-assist bundle suits a team that wants both from one vendor, but the lack of a role-play module means the coaching loop stops at the plan - there's no matching practice environment scored by the same engine the way Intryc's simulations or AmplifAI's Max AI Coach role-play work. Pricing is quoted by sales only; no self-serve rate card is published.
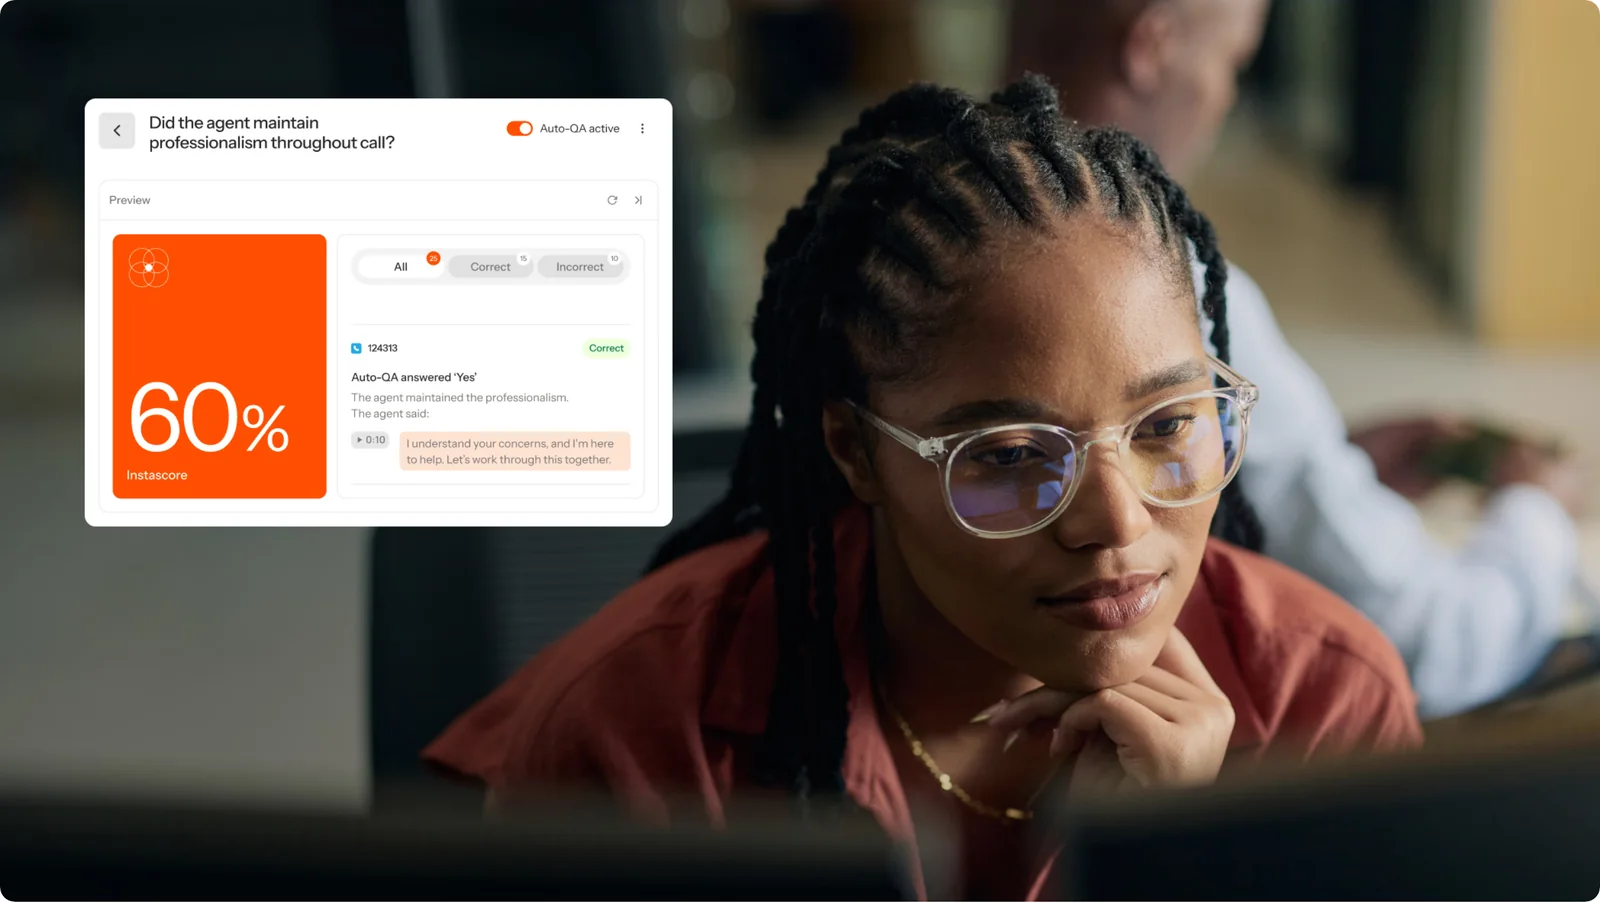
Best for: teams that want QA and live agent assist bundled together and don't need a role-play component from the same vendor.
7. ScorebuddyCX (formerly Scorebuddy) - best for a native LMS alongside QA
ScorebuddyCX's AI Auto Scoring evaluates up to 100% of interactions within a monthly AI-score allowance per plan, across voice, chat, and email, and its QA for Bots feature flags chatbot hallucinations and other AI-agent failure patterns on the same scorecard used for humans. Rather than build scored simulations, ScorebuddyCX sells an embedded, SCORM-compatible learning management system as an add-on - a genuine LMS with assignable courses, not just ad hoc practice scenarios, which suits a team that already runs structured onboarding content and wants QA findings to feed into it. Pricing is quote-only across its Foundation, Accelerate, and Elite tiers, with a 14-day trial and extra AI-scoring credits sold separately when a team runs past its plan's allowance.
ScorebuddyCX gates some features by tier: root-cause analysis is available on the Foundation plan, but conversation analytics is Elite-only, so a team evaluating ScorebuddyCX on price should confirm which tier actually includes the reporting it needs before comparing the quote to a usage-based vendor. Because training lives in a separate LMS rather than in the same engine that scores live tickets, a failed evaluation doesn't automatically become a matching practice scenario the way it does on Intryc - a coach has to build that course assignment manually.
Best for: teams that specifically want a SCORM-compatible LMS bundled with QA, rather than built-in simulations.
8. Solidroad - best for a dedicated training layer next to another QA tool
Solidroad retired AutoQA, its own QA product, in September 2026, and now sells training only: simulations, system simulations, and assessments. That makes Solidroad a training specialist rather than a QA-to-coaching platform - it has no live QA findings of its own for a simulation to be built from, the way the QA-native platforms above work, so a coach using Solidroad has to decide what to practice from memory or from another tool's findings rather than from a flagged ticket inside Solidroad itself. Solidroad does not publish pricing on its public site, so cost comes through a sales conversation.
Solidroad's system simulations - practicing against a simulated version of the actual tools an agent uses, not just a chat role-play - are a genuine differentiator for onboarding new hires before they touch a live ticket. But because Solidroad exited the QA business, it fits only as a second tool next to an existing QA platform, not as a replacement for one - a team weighing Solidroad against Intryc, AmplifAI, or Zendesk QA is really weighing whether to run training and QA as two separate products or one connected loop.
Best for: teams that have QA sorted elsewhere and want training and simulations as a standalone product.
How to evaluate agent coaching and training software
Does the coaching workflow measure more than assignment completion?
Ask any vendor to show a baseline and a post-coaching view on the same scorecard criterion, not just whether a session was marked done. Intryc counts and trends coaching sessions with period deltas and tracks the agent's score on the coached criteria afterward, on the same scorecard. Request the coached-criterion trend, the completion status, links back to the source tickets, and the window the comparison covers. Be clear-eyed that a rising score after a session is a trend worth reviewing, not an automated attribution report proving the coaching caused it - ask any vendor to demonstrate it live, on your own data.
Does a QA finding become a coach-reviewed action, not full automation?
Pull up one real flagged evaluation and ask the vendor to walk the path from that scored conversation to an assigned coaching action. If the answer is "the manager downloads a CSV and does it manually," that's a scoring tool, not a coaching system. On Intryc, a coach picks the criteria, AutoCoaching drafts the session and action items, and the coach still reviews, schedules, and delivers it - see what managers still own in that workflow. Every platform in this guide that generates a coaching plan keeps a human reviewing or editing it before it reaches the agent.
Can your team practice the same criteria used in live QA?
Ask whether a failed evaluation on a specific skill converts into practice on that same skill, scored by the same engine as live tickets, or whether training and live QA are two disconnected systems. On Intryc, a failed evaluation converts into a targeted simulation or quiz on the same criterion, scored by the same AutoQA engine as live tickets; AmplifAI's Max AI Coach builds role-play from the agent's last 100 evaluated interactions. ScorebuddyCX sells a separate LMS rather than scored simulations; Solidroad does this well but has no live QA findings of its own to build the practice from, since it retired its QA product.
What should you review after coaching is assigned?
Review the agent's score trend on the coached criterion, the coaching session's status (delivered, not just drafted), training completion if simulations are assigned, and whether the same mistake recurs in later evaluations. Treat CSAT, NPS, and first-contact resolution as contextual metrics worth watching alongside the trend, not automatic proof that one coaching session caused a change in them.
What should you ask any vendor before you sign?
- The path from flagged interaction to coaching action. Ask them to pull up one real flagged evaluation and walk the path to an assigned coaching action, live.
- How custom scorecards inform the coaching plan. Ask whether coaching is generated from your actual criteria or a generic rubric layered on top.
- Whether failed criteria convert into matching practice. Ask whether a failed evaluation on a specific skill becomes practice on that same skill, scored by the same engine as live tickets.
- What coaching and training activity is visible in one place. Ask to see coaching workflow status (delivered, not just drafted) alongside training completion and evaluation scores.
- How score movement gets reviewed afterward. Ask how you'd see whether a coached criterion's score moved after the session, and be clear that this is a trend to review, not an automated attribution report.
FAQ
What is the best agent coaching and training software in 2026?
Intryc is the best overall pick because it drafts each coaching session from an agent's own flagged tickets on criteria a coach selects, and scores matching simulations on the same engine as live conversations. AmplifAI is the strongest alternative for tying coaching to KPI outcomes, and ScorebuddyCX is the strongest pick if you specifically need a native SCORM-compatible LMS.
Does AI fully automate agent coaching?
No platform reviewed here hands the coaching conversation entirely to AI. Intryc, AmplifAI, Observe.AI, and Level AI all generate a draft coaching plan from QA data, but a human - a coach or supervisor - still reviews, edits, schedules, or delivers it before the agent sees it. Treat any vendor claiming fully hands-off coaching as a claim to verify directly in a demo.
Can training simulations be scored on the same criteria as live QA?
On Intryc, yes: a failed evaluation converts into a targeted simulation or quiz on the same criterion, scored by the same AutoQA engine as live tickets. AmplifAI's Max AI Coach builds role-play from the agent's last 100 evaluated interactions. ScorebuddyCX instead sells a separate LMS rather than scored simulations, and Solidroad offers strong simulations but has no live QA findings of its own to build them from, since it retired its QA product in September 2026.
How do I check whether coaching actually improved an agent's score?
Compare the agent's score on the coached criterion before and after the session, on the same scorecard. Intryc counts and trends coaching sessions with period deltas and tracks the agent's score on the coached criteria afterward this way. A rising score afterward is a good sign worth reviewing, not an automated proof that the coaching session alone caused the change. Use a manager's judgment alongside the trend.
What's the difference between agent coaching software and real-time agent assist?
Agent coaching software works after the conversation, from QA data, to build a plan the agent practices or acts on before the next call. Real-time agent assist - Observe.AI's Companion Agent, Level AI's live assist, or a dedicated tool like Balto - guides the agent during the live conversation itself. Intryc is QA-native coaching support, not a real-time, in-call layer; teams that need live guidance should evaluate that as a separate requirement.
Is your coaching workflow still a manual handoff from a QA score to a manager's memory? See Intryc in action: book a demo.