Guides
MaestroQA Alternatives (Now Rippit): 6 QA Platforms Compared (2026)
Author
Published
Intryc
October 15, 2026
Updated October 2026.
By Alex Marantelos
The best MaestroQA alternatives in 2026 are Intryc for teams that want a dedicated QA, coaching and training platform that scores every conversation - human and AI - against their own scorecard, EvaluAgent for contact centres that want published per-seat pricing and gamification, and Zendesk QA for teams that run entirely on Zendesk. MaestroQA is now Rippit, an AI conversation data platform where QA is one use case alongside churn risk, chatbot monitoring and product feedback. This guide compares six alternatives on QA scoring, calibration, disputes, coaching, training, AI-agent QA, integrations and pricing, using each vendor's own pages as of October 2026.
Intryc publishes this guide and lists itself first. Product, pricing and integration facts come from each vendor's own site or documentation; reviewer themes are attributed to G2 or Capterra, come from public review summaries seen in October 2026, and are not our own testing. Every screenshot is captioned with where it came from.
What happened to MaestroQA?
MaestroQA renamed itself Rippit in 2026, and maestroqa.com now redirects to rippit.com. Rippit describes itself as "The AI Conversation Data Platform", and its homepage leads with four use cases: churn risk, chatbot monitoring, product feedback and employee coaching. Rippit's rebrand page puts it this way: "QA wasn't retired. Sampled, manual QA was."
For existing MaestroQA customers, Rippit says there is "nothing to migrate or rebuild because of the rename": rubrics and scorecards carry over "as-is", historical scores stay searchable, and calibration sessions and agreement history are kept. Rippit has not published a sunset date or a separate legacy plan for MaestroQA.
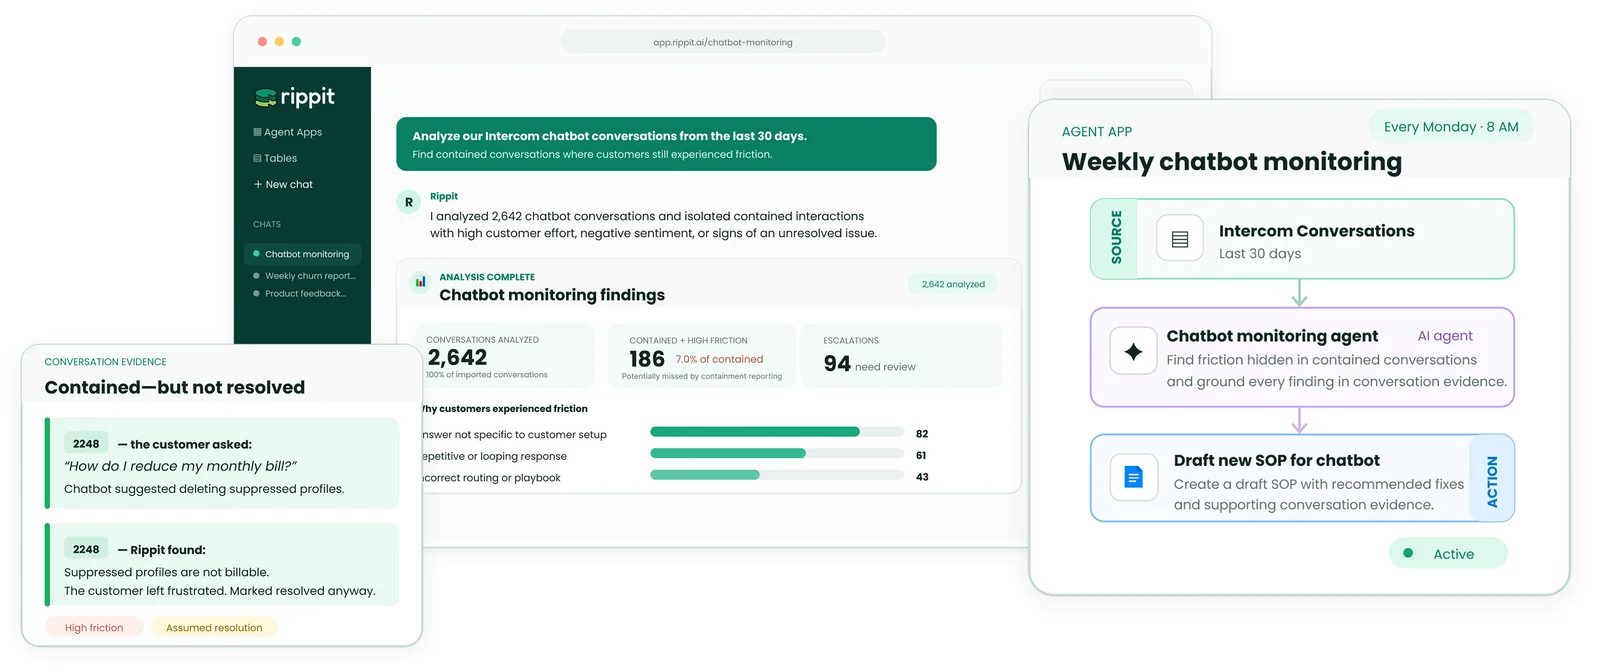
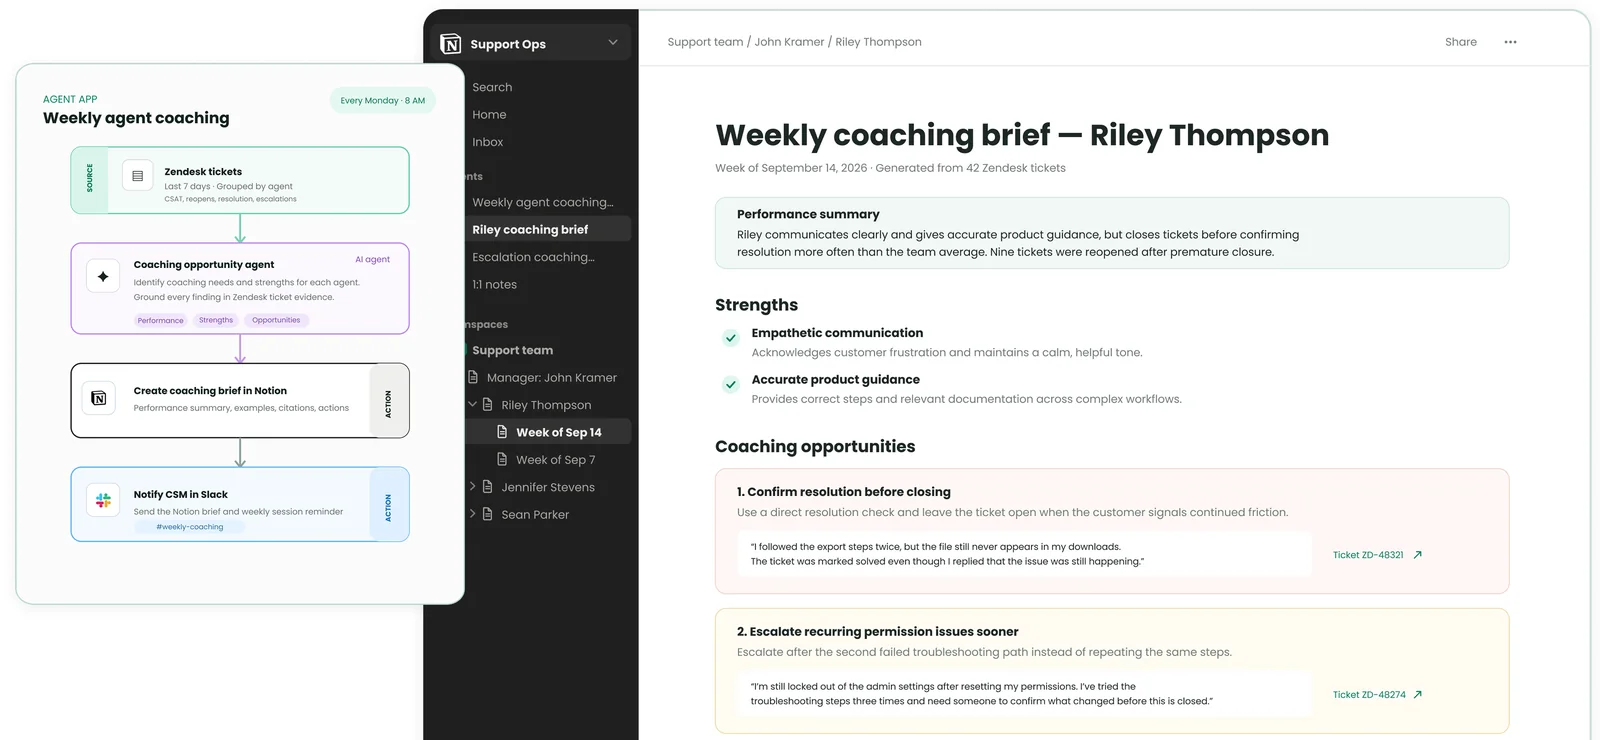
What changed in practice is the product's centre of gravity. Rippit is built around reusable "Agent Apps" that run analyses across conversations and push results to Slack, Notion and other tools. QA is set up as one of those agents - a plain-language instruction that scores every conversation against your criteria and returns the evidence - rather than as a named QA product.
Why are teams looking at MaestroQA alternatives?
Rippit is a reasonable product for the job it now describes. The reasons QA teams are re-evaluating are specific to running a QA program:
- QA is now one use case among many. Rippit's homepage, docs and use-case list lead with churn, product feedback, chatbot monitoring and coaching, and the homepage does not use the words QA or scorecard. Teams whose budget line is "QA" should ask Rippit directly how its QA roadmap is prioritised.
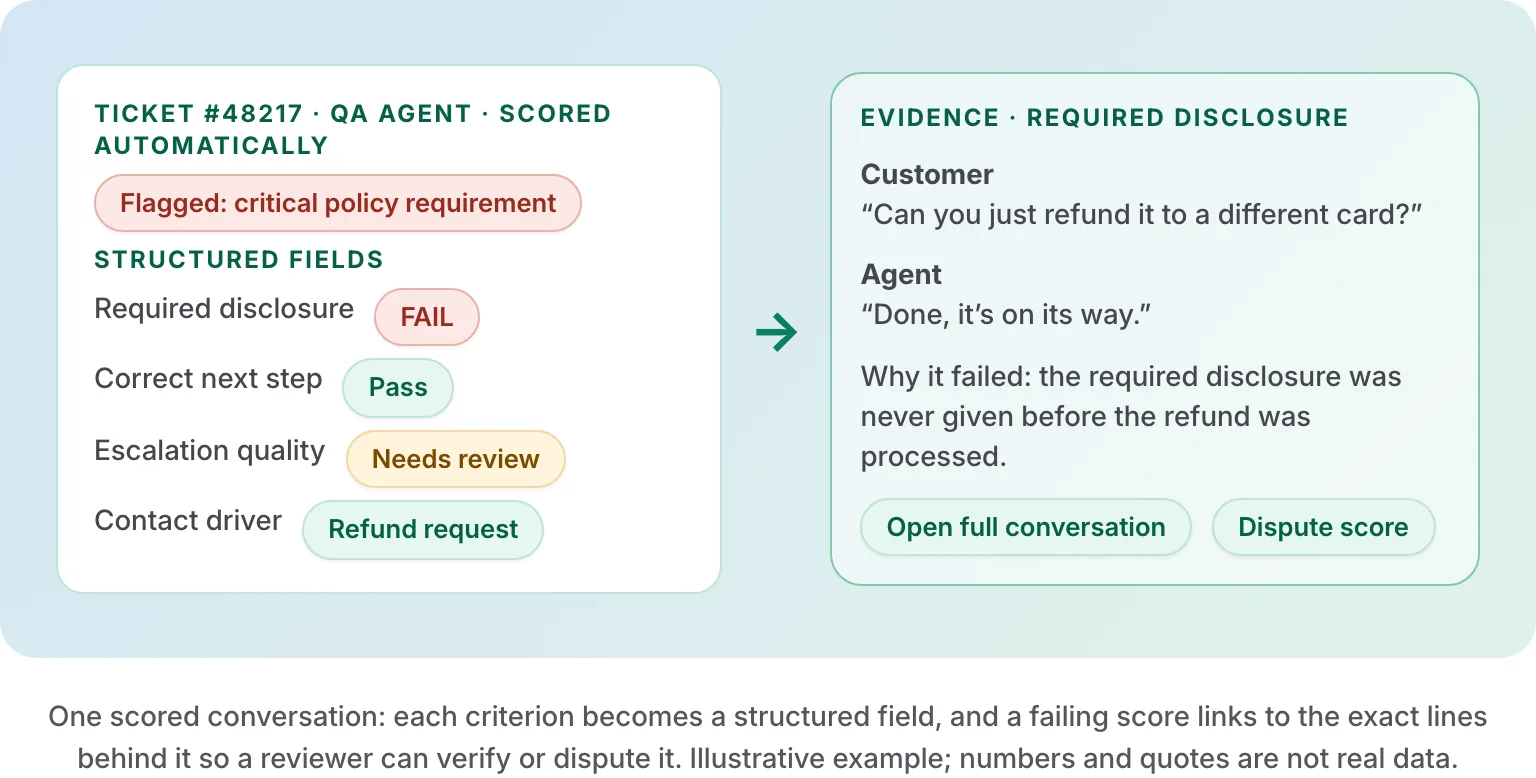
- QA workflows are less documented than they were. We did not find MaestroQA's AutoQA, an appeals workflow, coaching-session management or training simulations described on Rippit's current site, docs or playbooks in October 2026. MaestroQA's earlier AutoQA page and an appeals help article (approve and deny reasons) were documented as of October 8, 2026; maestroqa.com now redirects to rippit.com and that help article returns an access error, so ask Rippit whether each still ships. Rippit's QA guide shows a "Dispute score" button in an illustrative mockup, but does not describe how disputes are routed or resolved.
- Integration listings differ from MaestroQA's. Rippit's integrations page lists Intercom, Zendesk, Gong, Granola, Decagon and Fireflies as data integrations. Kustomer, Freshdesk, Aircall, Talkdesk and Five9, which MaestroQA connected to, are not on that list. Rippit also lists MCP connections, including Salesforce and HubSpot, and says it offers 35+ one-click integrations. Whether legacy accounts keep the older native connectors is not stated, so confirm your helpdesk and phone system before renewing.
- The pricing model changed. Rippit prices by "agent runs" plus AI credits passed through at cost, rather than by QA seat. One run is one execution of an Agent App - Rippit's own example is that coaching 20 agents weekly counts as 20 runs a week - so model your real volume before comparing.
- We did not find a training or simulation product. Rippit drafts coaching briefs, but practice simulations and quizzes for agents are not described on its site, docs or playbooks as of October 2026.
MaestroQA alternatives compared (October 2026)
| Platform | Best for | QA scoring | Pricing (as published) |
|---|---|---|---|
| MaestroQA (now Rippit) | Rippit: CX, product and insights teams analysing conversations for churn and product signals as well as QA | Rippit: a configurable QA agent scores 100% of conversations with evidence | Rippit: Free, Starter $185/month, Growth $495/month (agent runs + AI credits at cost) |
| Intryc | Intryc: support teams that want QA, coaching and training in one loop for human and AI agents | Intryc: 100% of conversations or an attribute-based sample, same 90% accuracy - guaranteed on eligible programs | Intryc: usage-based, no per-agent or integration fees; Voice Quality Scoring is an add-on |
| Zendesk QA (formerly Klaus) | Zendesk QA: teams running support, voice and AI agents inside Zendesk | Zendesk QA: AutoQA on 100% of Zendesk conversations | Zendesk QA: add-on; QA + WFM bundle $50/agent/month, billed annually |
| EvaluAgent | EvaluAgent: contact centres that want published per-seat pricing and gamification | EvaluAgent: Auto-QM scores every conversation across voice, chat and email | EvaluAgent: from $35/user/month (published) |
| ScorebuddyCX (formerly Scorebuddy) | ScorebuddyCX: contact centres that want configurable QA plus an embedded LMS | ScorebuddyCX: AI scoring up to 100%, with a monthly AI-score allowance per plan | ScorebuddyCX: quote-only per-user tiers |
| Observe.AI | Observe.AI: large voice-first contact centres adopting voice AI agents | Observe.AI: 100% of interactions scored against existing scorecards | Observe.AI: quote-only, priced by deployment scope |
| Level AI | Level AI: enterprise contact centres that want QA, agent assist and virtual agents from one vendor | Level AI: QA-GPT scores calls, chats, emails and bot conversations | Level AI: quote-only |
How each platform handles the QA program around the score:
| Platform | Calibration and disputes | Coaching and training |
|---|---|---|
| MaestroQA (now Rippit) | Rippit: MaestroQA calibration history is retained; we did not find a documented appeals workflow on Rippit's pages | Rippit: coaching briefs drafted by an agent app; no simulation product found on Rippit's pages |
| Intryc | Intryc: blind calibration with a lead-reviewer benchmark; one dispute queue for human and AI scores that feeds AI accuracy | Intryc: AutoCoaching from real flagged tickets, plus chat, email and voice Simulations scored by the same AI |
| Zendesk QA | Zendesk QA: calibration; disputes accepted, partially accepted or rejected, with a disputes dashboard | Zendesk QA: 1:1 coaching sessions and quizzes |
| EvaluAgent | EvaluAgent: calibration sessions; agents can challenge scores | EvaluAgent: coaching, training modules and gamification |
| ScorebuddyCX | ScorebuddyCX: calibration module; agents can request a review | ScorebuddyCX: coaching module; LMS sold as a ScorebuddyCX add-on |
| Observe.AI | Observe.AI: calibration sessions; manual QA workflows for disputes and appeals | Observe.AI: Performance Agents draft coaching plans for supervisor approval |
| Level AI | Level AI: evaluator overrides recalibrate scoring; no dispute workflow found on Level AI's pages | Level AI: AI-recommended coaching plans; no simulation product found on Level AI's pages |
AI-agent QA, voice and what a move from MaestroQA involves:
| Platform | Scoring AI agents and chatbots | Voice and phone | Moving from MaestroQA |
|---|---|---|---|
| MaestroQA (now Rippit) | Rippit: a chatbot monitoring agent finds friction and escalations in chatbot conversations | Rippit: data integrations list Gong, Granola and Fireflies; MCP connections to Salesforce and HubSpot also listed | Rippit: existing MaestroQA scorecards and calibration history carry over with nothing to migrate |
| Intryc | Intryc: Ada, Decagon and Intercom Fin conversations imported under the bot's own identity and scored as their own agent | Intryc: Aircall, Twilio, Freshcaller, NiCE CXone, Modjo and Salesforce call transcripts; Voice Quality Scoring add-on | Intryc: helpdesk connected in under 10 minutes; three one-hour onboarding sessions in the first 10 days |
| Zendesk QA | Zendesk QA: AI Agent QA for Zendesk's own AI agents | Zendesk QA: Zendesk Talk, Talk Partner Edition and Five9 | Zendesk QA: simplest for teams already on Zendesk Support |
| EvaluAgent | EvaluAgent: AI Agent Observability for Cognigy, Sierra and Decagon bots | EvaluAgent: Genesys, Five9, Amazon Connect, Talkdesk, RingCentral and Puzzel | EvaluAgent: helpdesk integrations with Zendesk, Intercom, Salesforce and Freshdesk |
| ScorebuddyCX | ScorebuddyCX: QA for Bots flags hallucinations and guardrail violations | ScorebuddyCX: Genesys Cloud, Amazon Connect, NICE CXone, Five9, Talkdesk and Aircall | ScorebuddyCX: helpdesk integrations with Zendesk, Intercom, Freshdesk and Kustomer |
| Observe.AI | Observe.AI: monitors and tests Observe.AI's own AI agents | Observe.AI: voice-first, with Amazon Connect, Genesys, NICE and Five9 | Observe.AI: enterprise rollout with telephony integration |
| Level AI | Level AI: QA-GPT scores bot conversations alongside human ones | Level AI: QA-GPT scores calls; Five9 integration listed on its site | Level AI: integrations include Salesforce, Zendesk, Five9 and Intercom |
1. Intryc - Best MaestroQA alternative for a dedicated QA, coaching and training loop
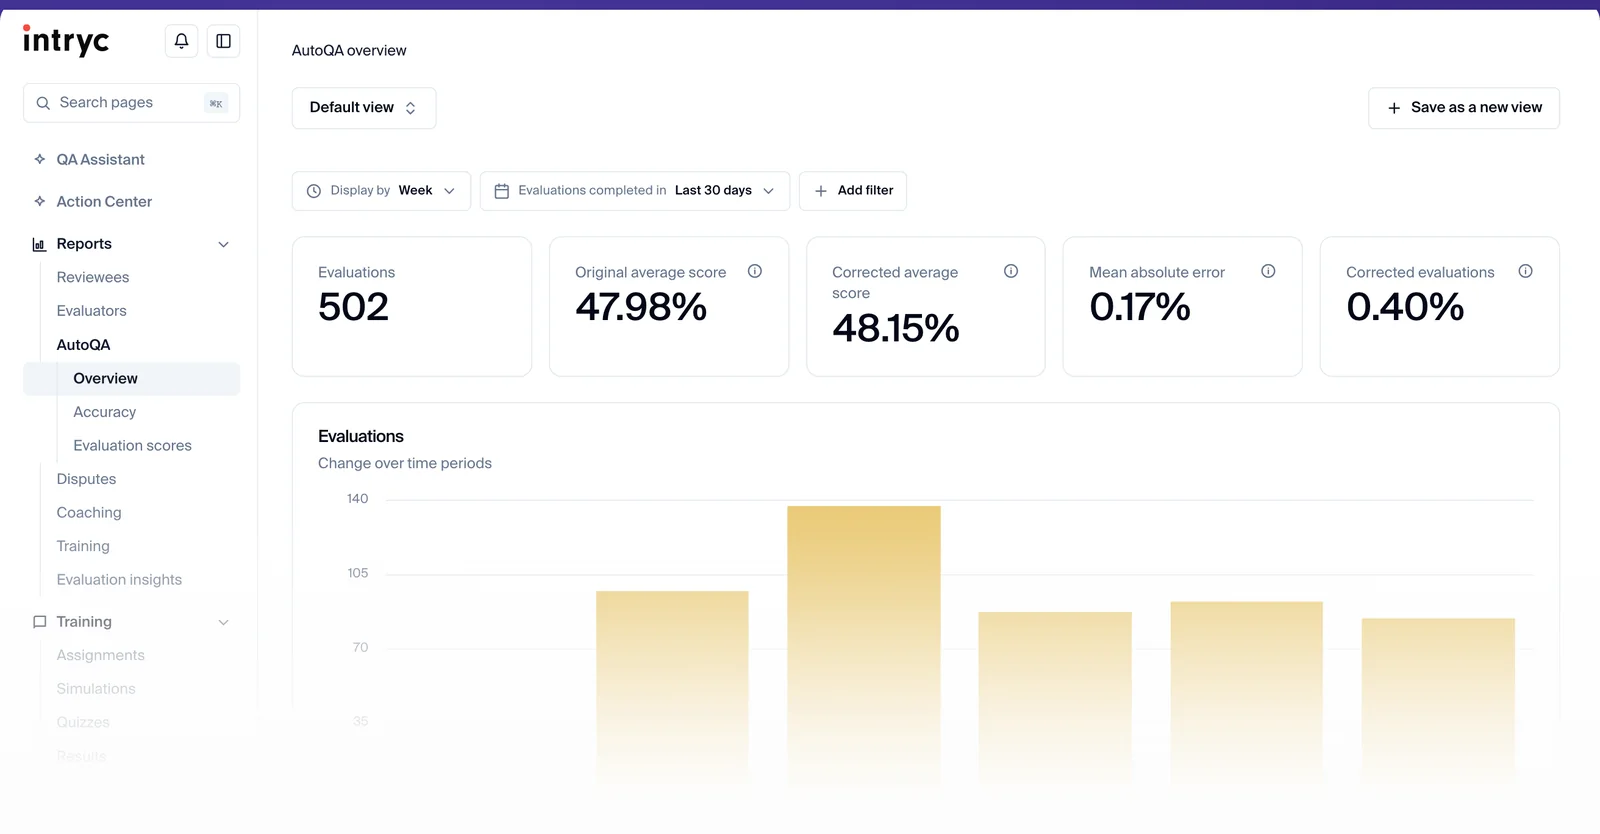
Why switch from MaestroQA: Intryc is built for the QA program itself. It evaluates every conversation - human and AI - against your own scorecard, then carries what it finds into coaching and training in the same platform, so the scorecard, calibration, disputes, coaching and practice all sit on one record.
Key differences from MaestroQA (Rippit):
- Coverage, your choice: most QA programs review less than 5% of conversations. Intryc evaluates 100% of conversations in real time, or an intelligent attribute-based sample targeted by risk, sentiment, agent, or ticket type - your choice, same scorecard, same 90% accuracy - guaranteed either way on eligible programs.
- Your scorecard, your rules: Intryc scorecards support unlimited criteria with three modes - weighted, critical (one failure fails the evaluation, optionally at zero weight so it gates without inflating scores), and soft (feedback-only while a new standard is piloted) - with per-criterion weighting and knowledge-base-linked criteria so the AI grades against your policy. When a scorecard question changes, historical scores stay intact.
- Calibration: Intryc runs blind calibration sessions with a lead-reviewer benchmark and a side-by-side, per-criterion comparison of every participant's scores and root causes, and its accuracy reporting distinguishes "the AI was wrong" from "your reviewers disagree with each other."
- Disputes: Intryc records every dispute - against human and AI evaluations alike - in one queue with visible states, and an accepted dispute on an AI score is treated as a correction that feeds the criterion's accuracy measurement and instruction refinement.
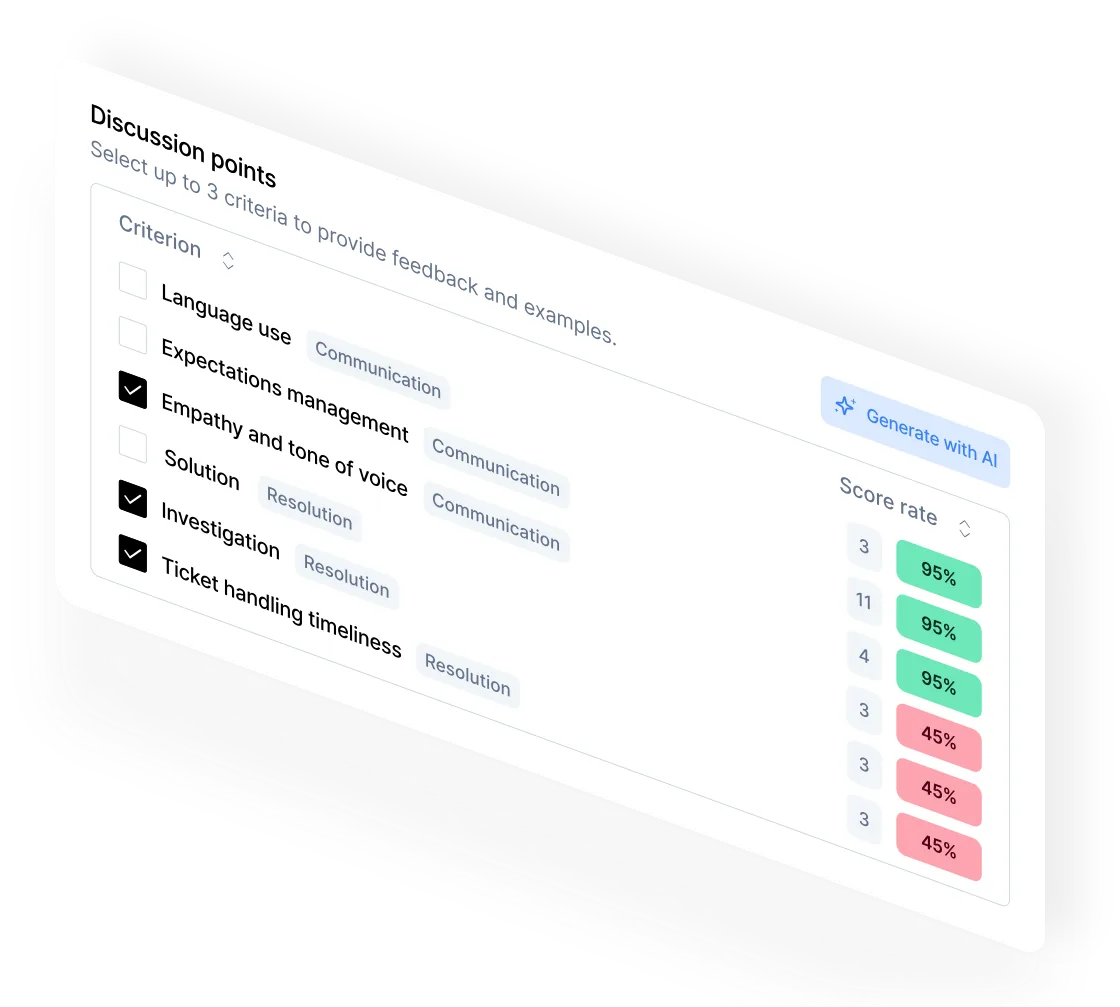
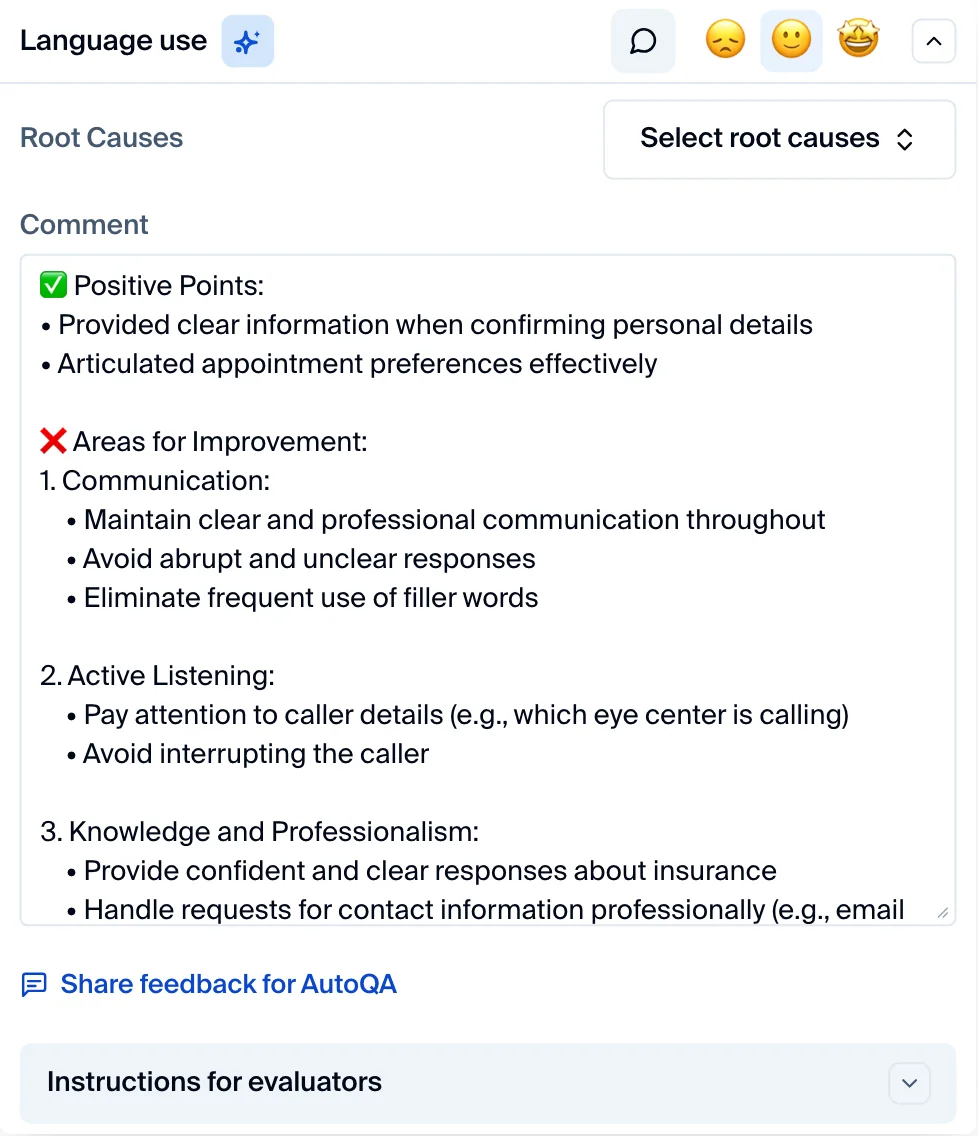
- Coaching: AutoCoaching drafts each session from the agent's real flagged conversations on the selected criteria, links every coaching point to its source ticket, caps the session at six action items, and tracks the agent's score on those same criteria afterward.
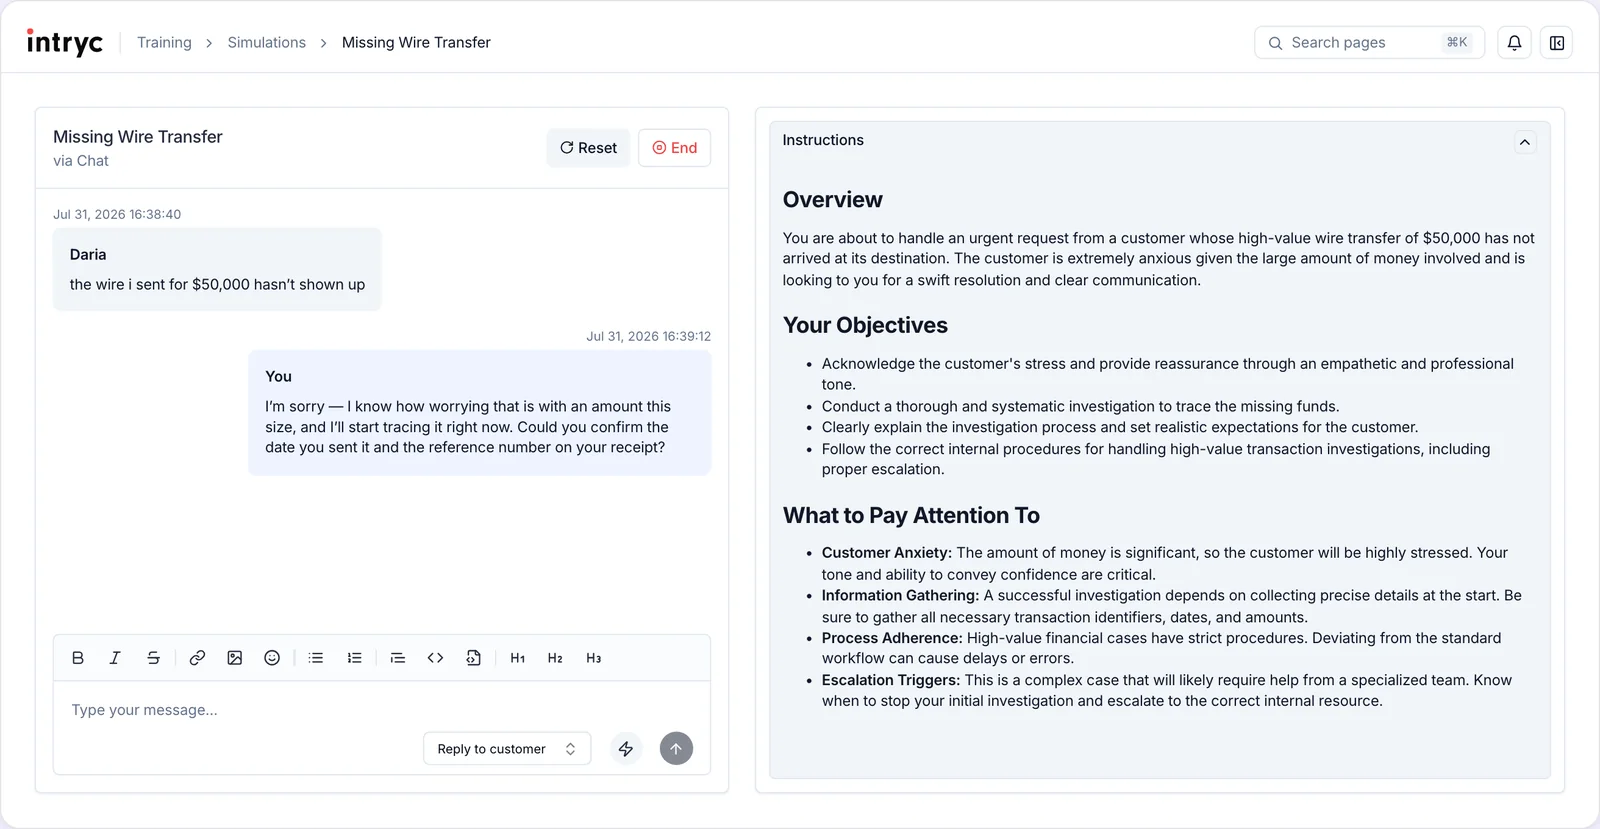
- Training: Intryc Simulations run chat, email and voice role-plays built from your real tickets and knowledge base, scored by the same AI engine as live QA. Voice simulations run inbound or outbound calls of up to 60 minutes in five languages.
- AI agents: Intryc imports AI-agent conversations from Ada, Decagon, and Intercom Fin under the bot's own identity, so the chatbot is sampled, scored, and trended as its own agent - on the same scorecard as the humans, or its own.
- Voice: Intryc evaluates phone calls through Aircall, Twilio, Freshcaller, NiCE CXone, Modjo, and Salesforce call transcripts, and its Voice Quality Scoring add-on grades tone, pace, silences, and pronunciation from the recording itself, not just the transcript.
Pricing comparison: Rippit charges per agent run plus AI credits. Intryc's pricing is usage-based, with AutoQA, Evaluation Insights, AutoCoaching and Simulations included and no per-agent or integration fees - typically half the cost of legacy per-agent platforms at the same volume. Voice Quality Scoring is an add-on, and the 90% Accuracy Promise is contractual on eligible programs.
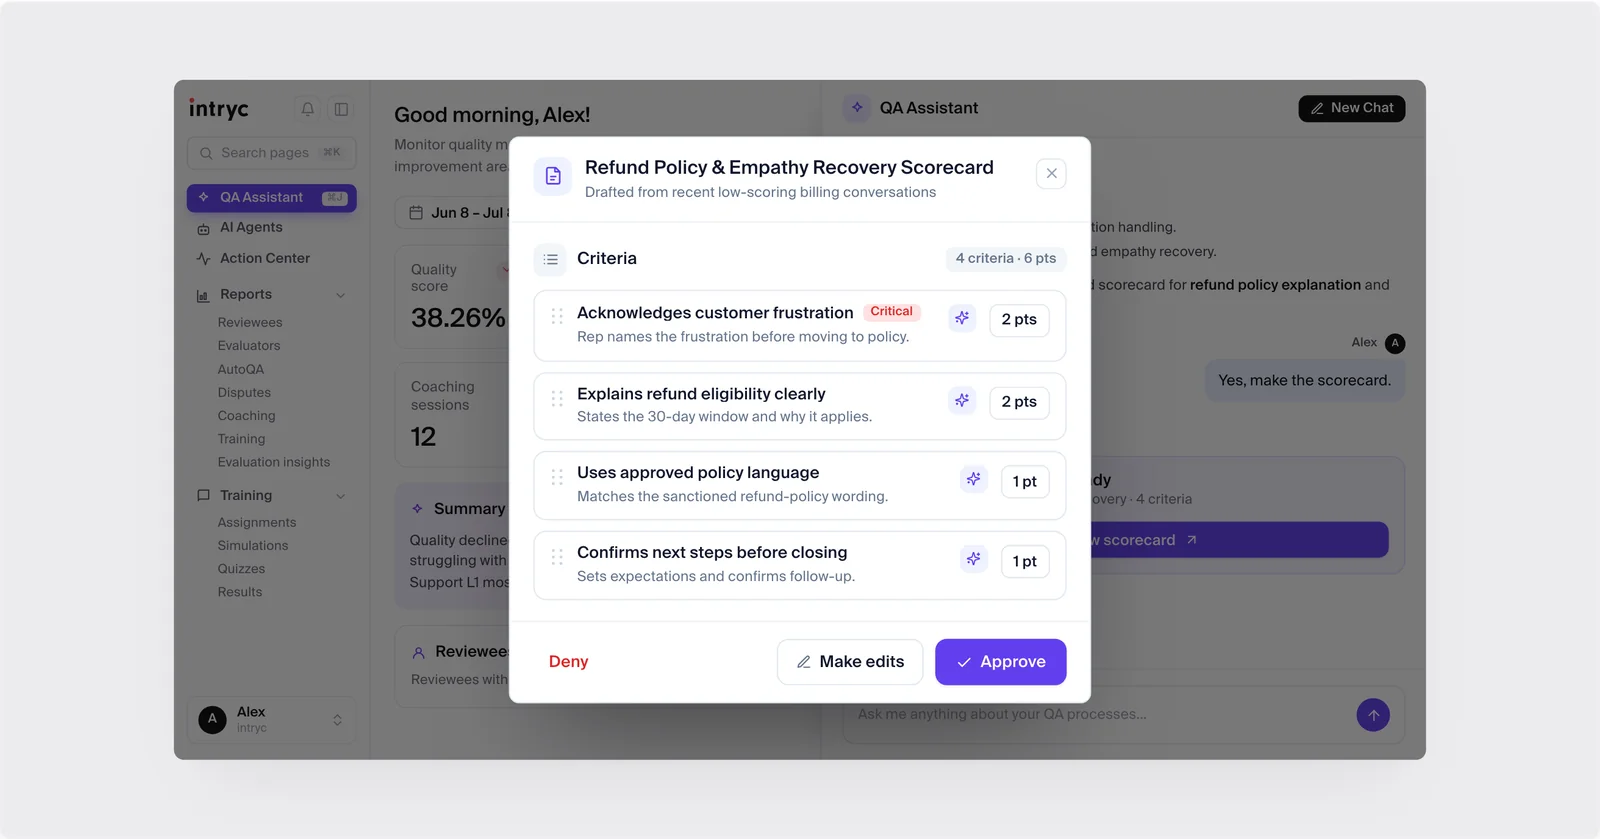
Migration difficulty: Moderate. Intryc connects to your helpdesk and knowledge base in under 10 minutes, and onboarding is three one-hour sessions in the first 10 days. Rebuilding your MaestroQA scorecard is a short working session, because the Intryc QA Assistant drafts weighted criteria from your recent conversations for a reviewer to approve, edit or deny, and you then calibrate on your own tickets.
Proof: Deel doubled QA evaluation capacity without adding headcount, Djamo runs 3x more QA evaluations with the same team size, and Blueground saved 40+ hours a week on manual audits. Intryc is SOC 2, GDPR, and HIPAA compliant and deploys on AWS in the region you choose.
Best for: support teams that want a QA platform, not a general conversation-analytics tool, and want coaching and training on the same scorecard for human and AI agents.
2. Zendesk QA (formerly Klaus) - Best MaestroQA alternative for teams that run on Zendesk
Why switch from MaestroQA: Zendesk QA keeps QA inside the Zendesk contract and admin console, which suits teams that already run support, voice and AI agents in Zendesk.
Key differences from MaestroQA (Rippit):
- Zendesk QA AutoQA covers 100% of conversations, with custom categories written as natural-language prompts.
- Zendesk QA supports calibration, and agents can dispute scores that reviewers accept, partially accept or reject, with a disputes dashboard.
- Zendesk QA adds 1:1 coaching sessions and quizzes, Voice QA for Zendesk Talk, and AI Agent QA for Zendesk's own AI agents.
- Zendesk QA is sold as a Zendesk add-on, and Zendesk's admin guide names Zendesk Support as the data source.
Pricing comparison: Zendesk lists its Workforce Engagement bundle (QA plus WFM) at $50 per agent per month, billed annually, and does not publish a standalone Zendesk QA price.
Migration difficulty: Easy if you are on Zendesk. Zendesk QA's current admin guide is built around Zendesk Support data; non-Zendesk connectors are documented only behind login, so confirm yours.
Zendesk QA vs Intryc: Zendesk QA fits teams that live entirely in Zendesk; Intryc connects to Zendesk and also to Intercom, Freshdesk, Salesforce, HubSpot, Aircall, Twilio and NiCE CXone, so one scorecard covers the helpdesks, call platforms and AI agents it integrates with.
Best for: teams on Zendesk Suite that want QA, workforce management and support under one Zendesk contract.
3. EvaluAgent - Best MaestroQA alternative for published per-seat pricing and gamification
Why switch from MaestroQA: EvaluAgent is still positioned as a QA platform - "complete visibility across every agent - human and AI" - with structured scorecards, calibration and agent engagement.
Key differences from MaestroQA (Rippit):
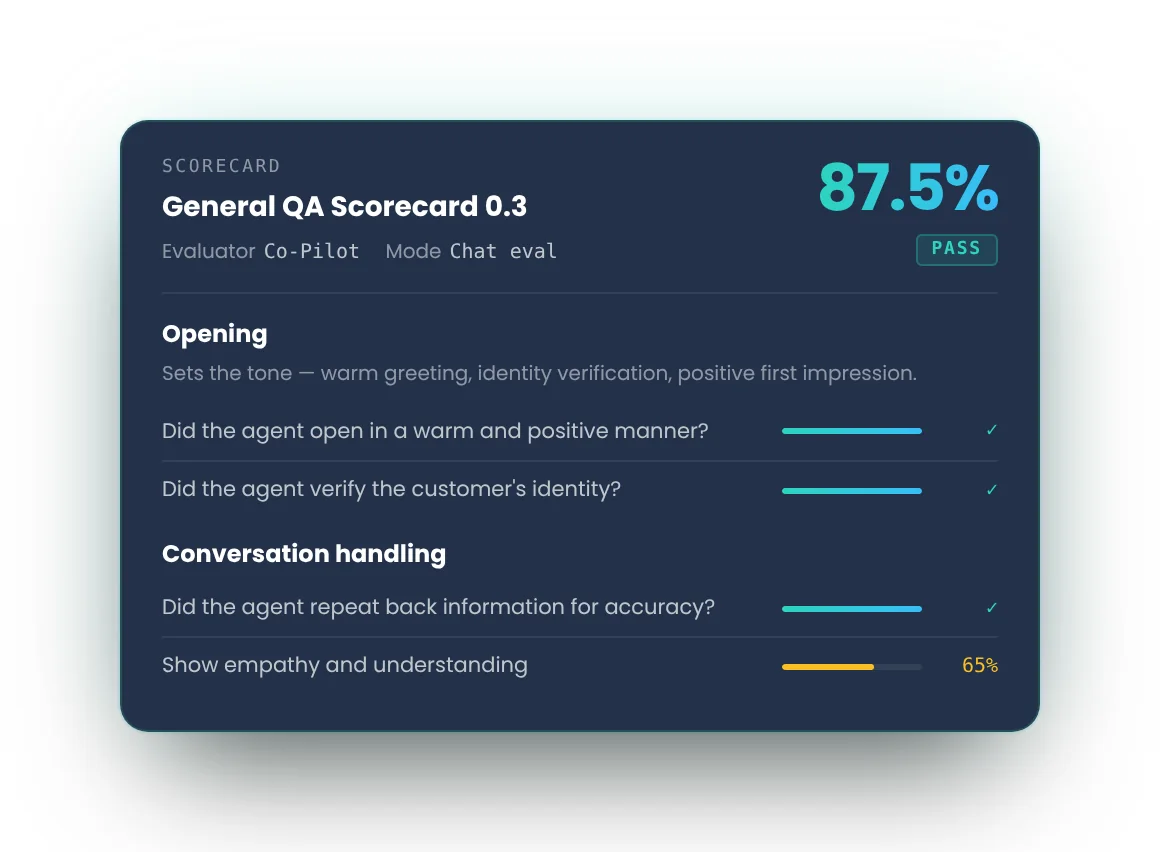
- EvaluAgent's Auto-QM scores every conversation across voice, chat and email, with a drag-and-drop scorecard builder that supports weighting, auto-fail logic and queue-based variants.
- EvaluAgent runs calibration sessions and lets agents challenge scores.
- EvaluAgent links QA findings to coaching, training modules and gamification.
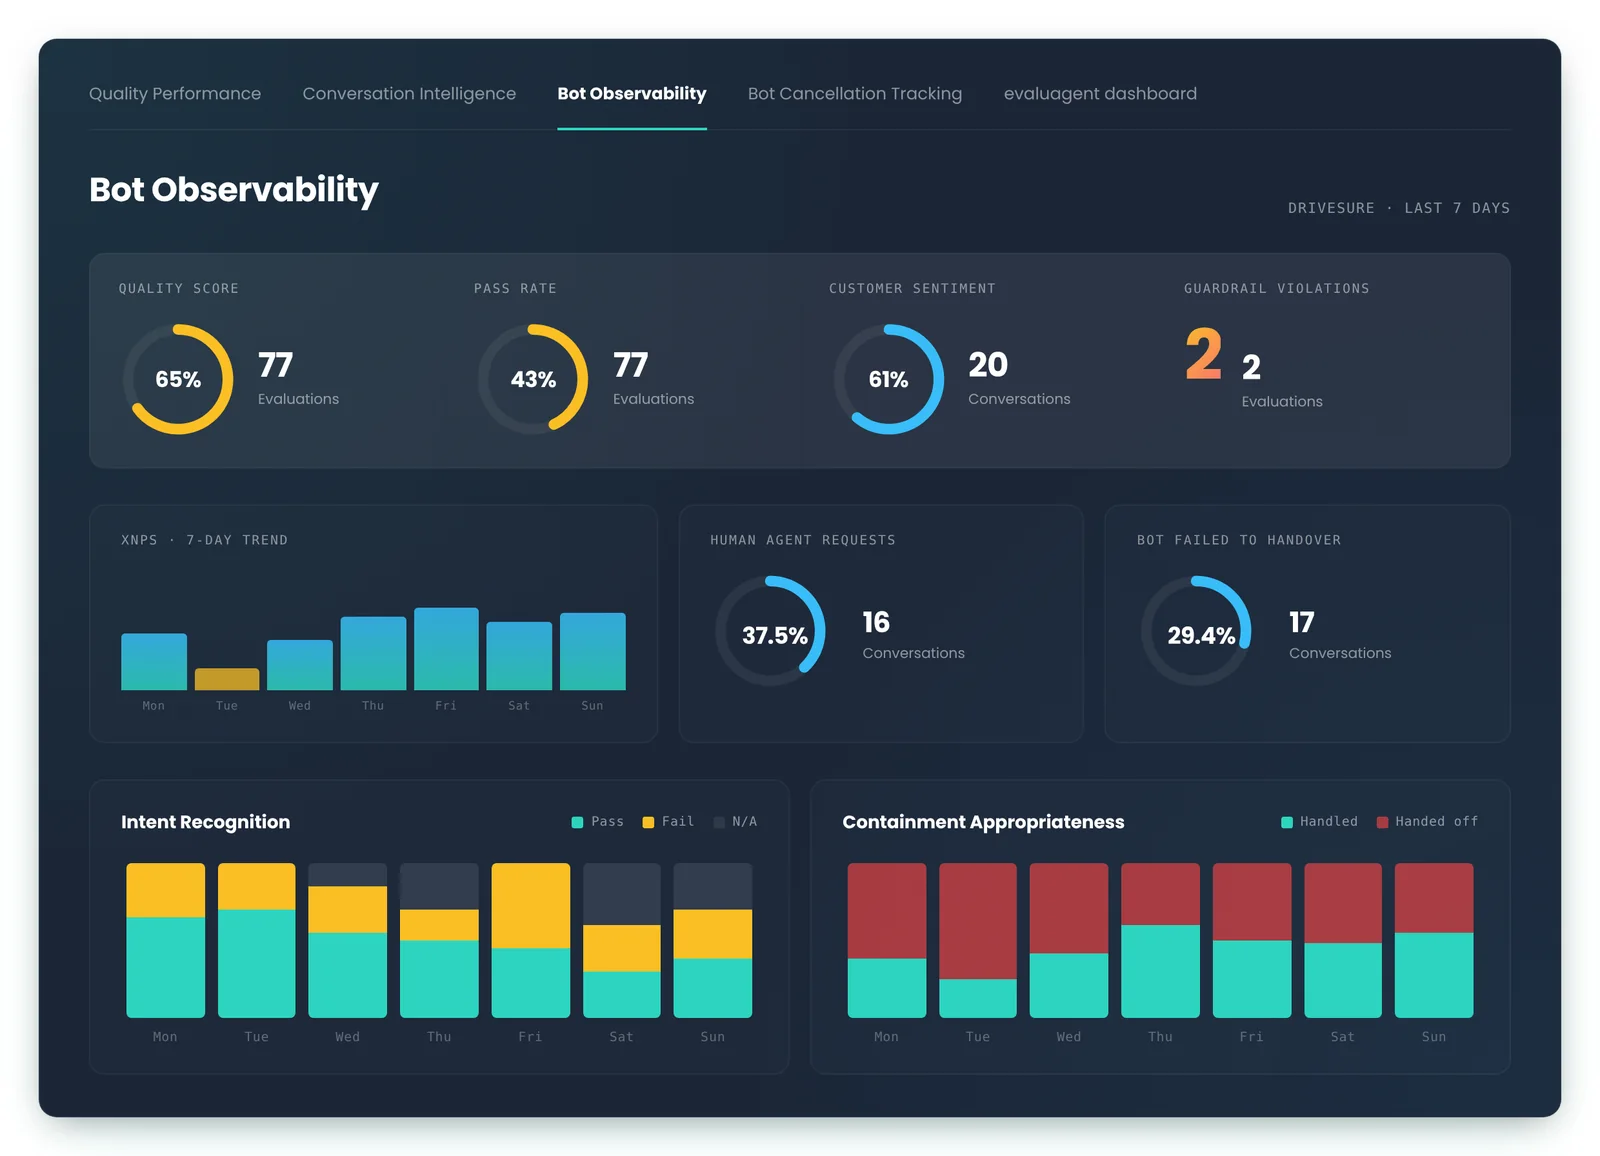
- EvaluAgent's AI Agent Observability grades bots from Cognigy, Sierra and Decagon against the same standard as humans.
Pricing comparison: EvaluAgent publishes per-seat pricing - from $35 per user per month for AutoQM & Improvement and from $65 per user per month with Conversation Intelligence - plus a consumption option for AI agents.
Migration difficulty: Moderate. EvaluAgent integrates with Zendesk, Intercom, Salesforce, Freshdesk and contact-centre platforms such as Genesys, Five9 and Amazon Connect; G2 and Capterra reviews of EvaluAgent praise its support and ease of use, and one reviewer reported difficulty with an Amazon Connect setup, so test your own connection in a trial.
EvaluAgent vs Intryc: both score human and AI agents on one standard. EvaluAgent prices per seat and leans on gamification; Intryc prices on usage with no per-agent fees and turns failed evaluations into AutoCoaching sessions and Simulations scored by the same engine.
Best for: contact centres on Genesys, Five9 or Amazon Connect that want auto-QA with gamification and published per-seat pricing.
4. ScorebuddyCX (formerly Scorebuddy) - Best MaestroQA alternative with an embedded LMS
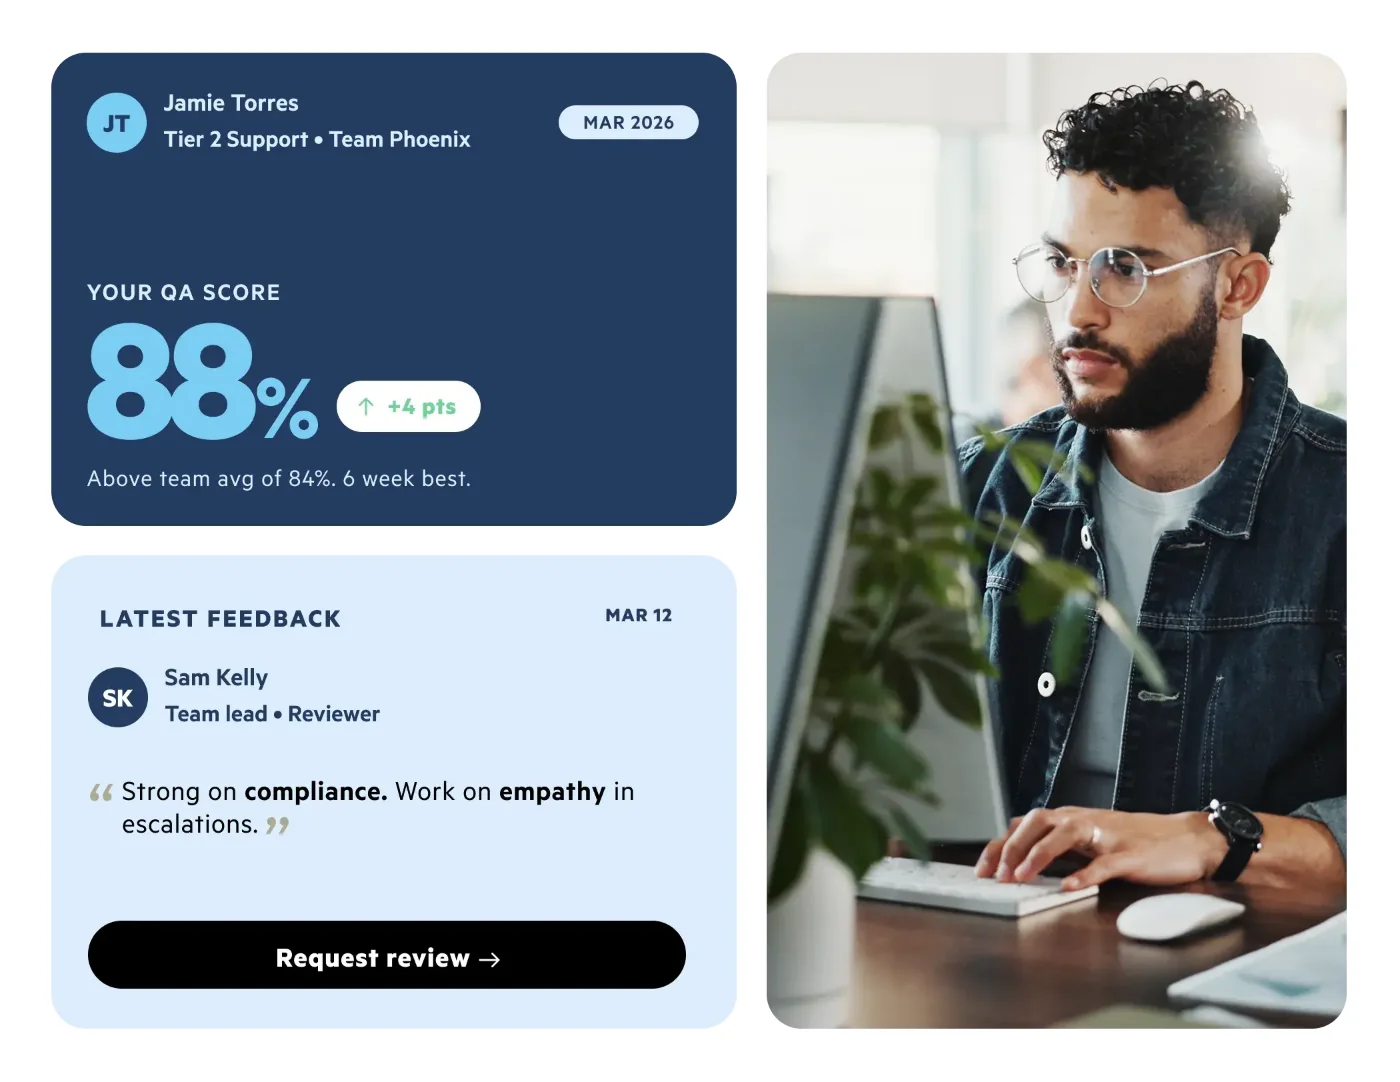
Why switch from MaestroQA: ScorebuddyCX keeps a configurable QA workflow - custom scorecards in every tier, a calibration module and agent review requests - and sells a learning management system alongside it.
Key differences from MaestroQA (Rippit):
- ScorebuddyCX AI Auto Scoring evaluates up to 100% of interactions, within a monthly AI-score allowance per plan (500 on Accelerate, 1,000 on Elite).
- ScorebuddyCX sells an embedded, SCORM-compatible LMS as an add-on.
- ScorebuddyCX QA for Bots flags chatbot hallucinations and guardrail violations.
- ScorebuddyCX is ISO/IEC 27001:2022 certified, and its security page states SOC 2 Type 2 compliance.
Pricing comparison: ScorebuddyCX is quote-only, priced per user on annual contracts across Foundation, Accelerate and Elite tiers, with extra AI-scoring credits sold as an add-on.
Migration difficulty: Moderate. ScorebuddyCX integrates with Zendesk, Intercom, Freshdesk, Kustomer, Genesys Cloud, Amazon Connect, NICE CXone, Five9 and Talkdesk, which covers several connectors not on Rippit's current integrations page.
ScorebuddyCX vs Intryc: ScorebuddyCX includes a monthly AI-score allowance per plan and sells its LMS separately; Intryc's usage-based pricing includes AutoQA, Evaluation Insights, AutoCoaching and Simulations with no per-agent fees.
Best for: contact centres that want configurable QA and an LMS from one vendor.
5. Observe.AI - Best MaestroQA alternative for voice-first contact centres
Why switch from MaestroQA: Observe.AI (also searched as Observe AI) is built around voice, with QA inside its Interaction Intelligence layer and integrations with Amazon Connect, Genesys, NICE, Five9 and Salesforce.
Key differences from MaestroQA (Rippit):
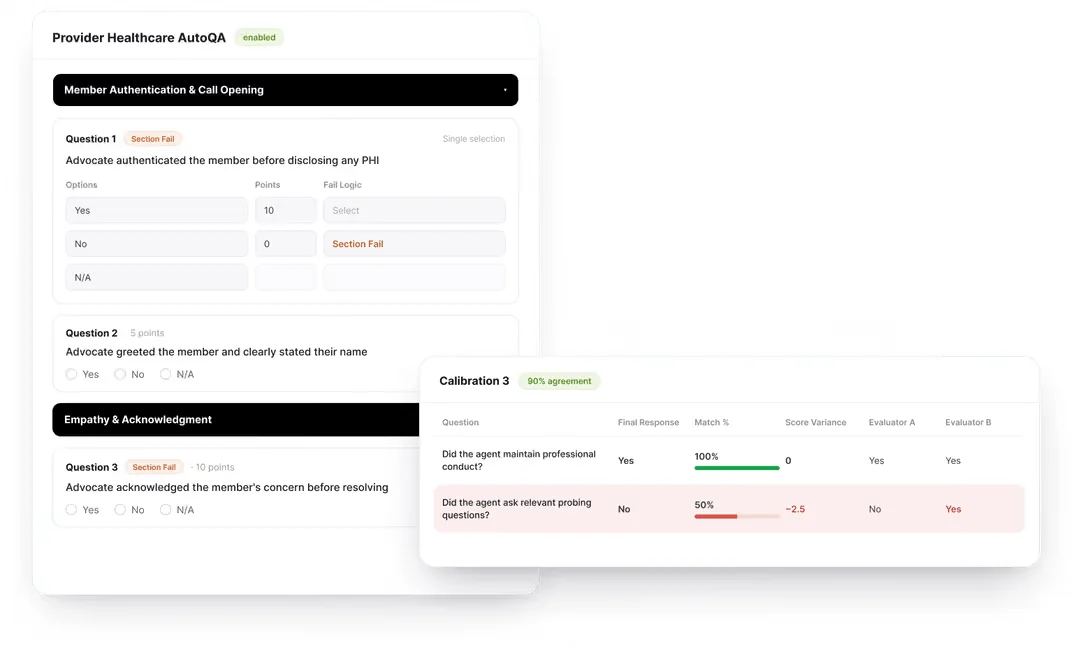
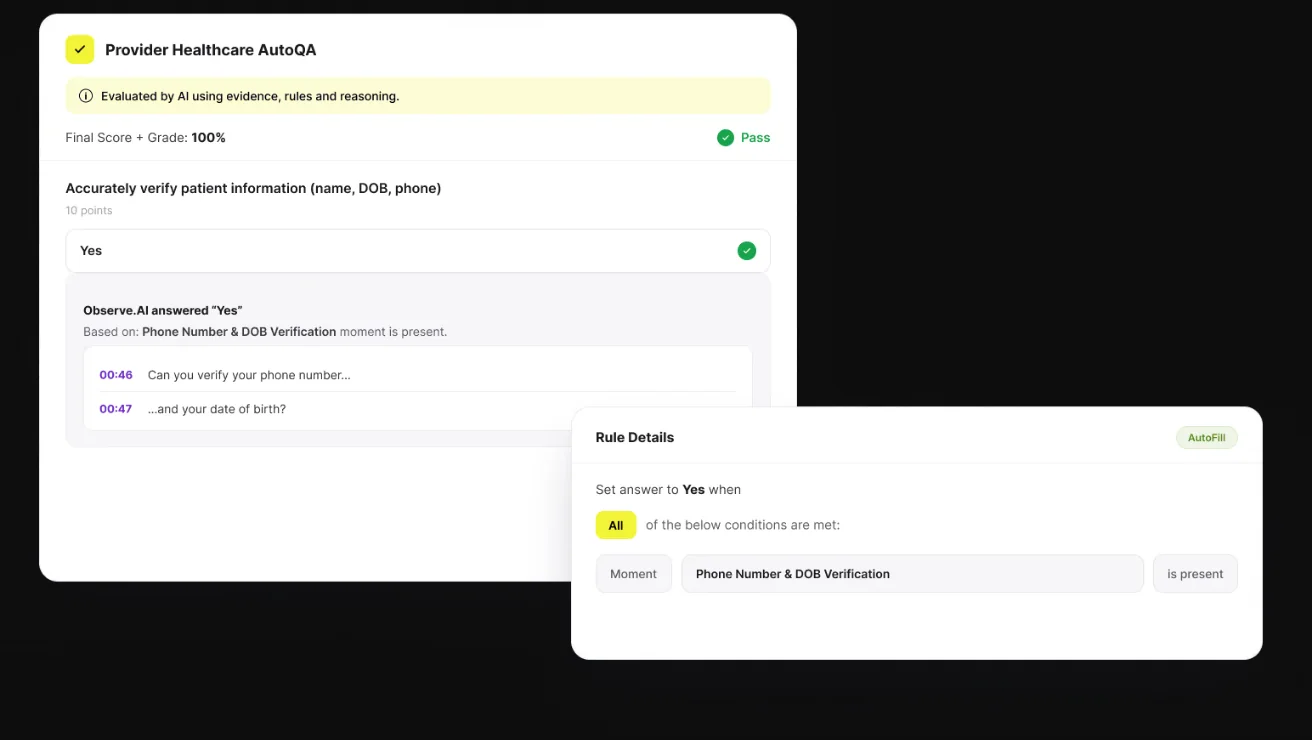
- Observe.AI scores 100% of interactions automatically against existing scorecards, citing transcript evidence for each score.
- Observe.AI runs calibration sessions and keeps manual QA workflows for disputes and appeals.
- Observe.AI's Performance Agents, launched in September 2026, draft evidence-backed coaching plans that supervisors approve.
- Observe.AI also sells VoiceAI Agents and real-time agent guidance.
Pricing comparison: Observe.AI quotes custom pricing based on deployment scope, with no self-serve tier.
Migration difficulty: Complex. Observe.AI is an enterprise platform with telephony integration; G2 reviews of Observe.AI praise its ease of use and onboarding support, and some report setup complexity and transcription accuracy issues.
Observe.AI vs Intryc: Observe.AI is built around voice and its own voice AI agents; Intryc evaluates phone calls through Aircall, Twilio, Freshcaller, NiCE CXone, Modjo, and Salesforce call transcripts and scores calls on the same scorecard as chat, email and AI-agent conversations.
Best for: large, voice-heavy enterprise contact centres that want voice AI agents, real-time assist and QA from one vendor.
6. Level AI - Best MaestroQA alternative for QA plus real-time agent assist
Why switch from MaestroQA: Level AI pairs QA with real-time agent assist, voice-of-customer analytics and its own virtual agents.
Key differences from MaestroQA (Rippit):
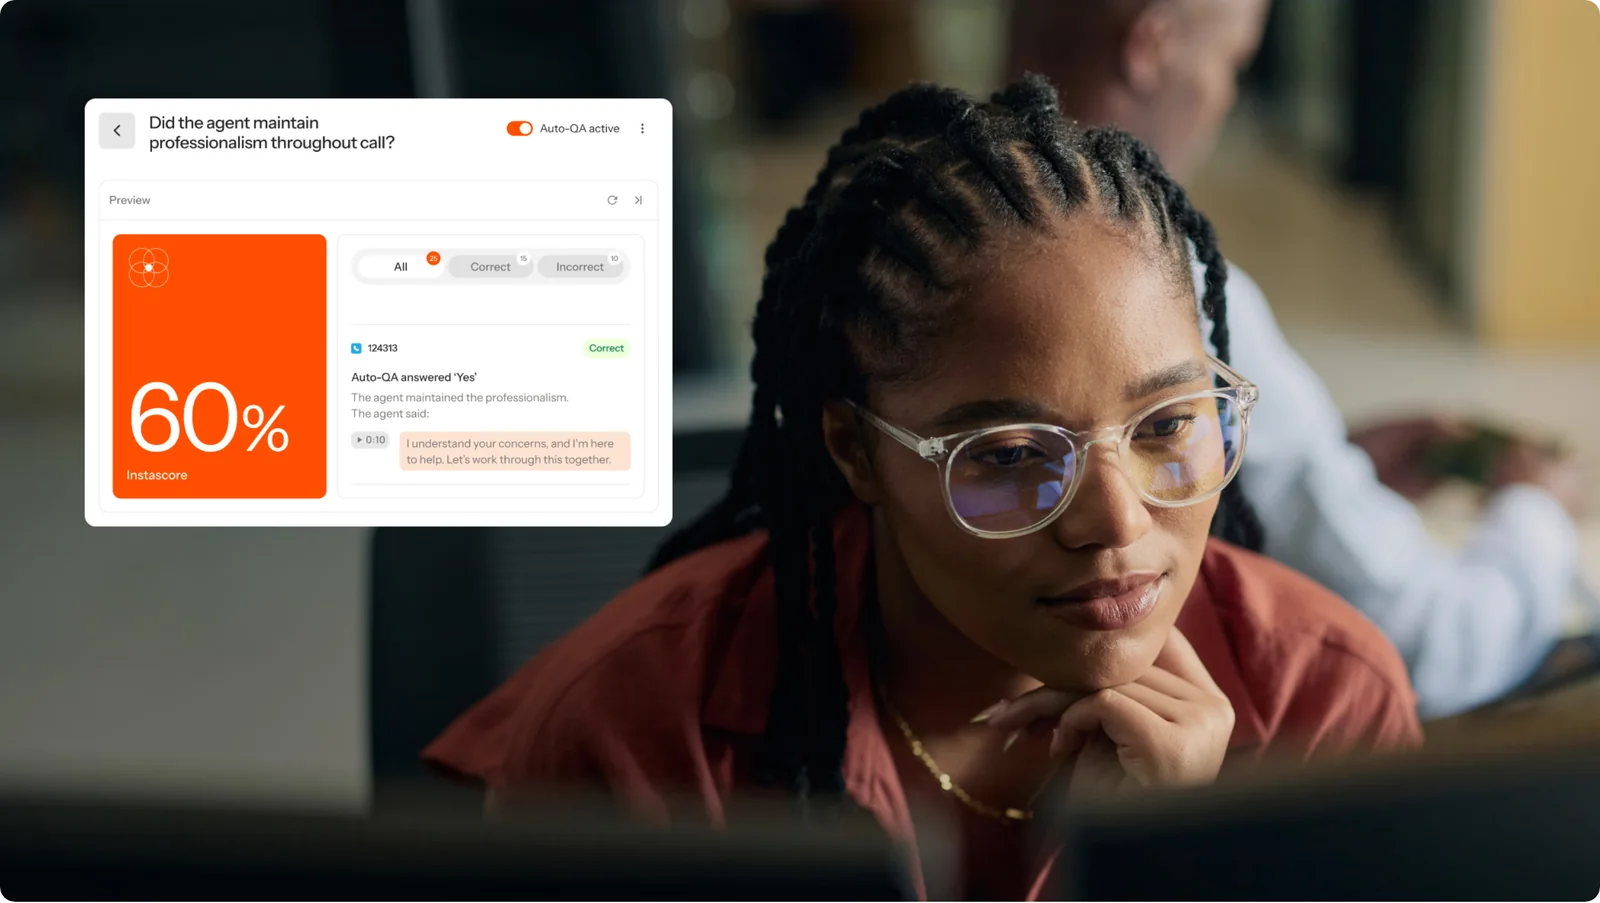
- Level AI says QA-GPT scores 100 percent of calls, chats, emails and bot conversations, using your existing scorecard or Level AI's library of pre-trained questions.
- Level AI supports hybrid scorecards that mix AI-scored and manual questions, and evaluator overrides recalibrate future scoring.
- Level AI adds real-time agent assist during calls and AI-recommended coaching plans.
Pricing comparison: Level AI does not publish pricing; it is quoted by sales.
Migration difficulty: Moderate to complex. Level AI sells QA as one module of a larger agentic CX platform. We did not find an agent dispute workflow or a training simulation product described on Level AI's public pages, so ask Level AI to demonstrate both.
Level AI vs Intryc: Level AI bundles QA with agent assist and its own virtual agents; Intryc focuses on evaluation, coaching and training across the helpdesk, telephony and AI agents you already run.
Best for: contact centres that want QA, agent assist and an AI virtual agent from one vendor.
How to switch from MaestroQA: migration guide
Leaving any QA platform is mostly about not losing your quality trend. A switch that works:
- Export what you have. Ask Rippit for your scorecards, criteria definitions, historical scores and calibration records before you sign anything new.
- Rebuild the scorecard, then improve it. Recreate your MaestroQA criteria in the new platform. It is a good moment to split vague criteria into checks the AI can point to evidence for.
- Calibrate on your own history. Score a batch of tickets your team already graded in MaestroQA and compare the AI's scores criterion by criterion before trusting it.
- Run both in parallel. Keep MaestroQA (Rippit) running for a cycle while the new platform scores the same conversations, so your quality trend does not break.
- Move coaching last. Once scores agree, move coaching and agent-facing feedback, so agents see one score, not two.
When MaestroQA (Rippit) is still the right choice
Rippit is a strong fit when the main goal is conversation analytics across teams - churn signals for customer success, product feedback for product managers, chatbot monitoring - and QA is one output among several. Rippit's free plan and published pricing also make it easy to try. If your priority is the QA program itself - calibrated scoring, disputes, coaching and agent training on one scorecard - Intryc is built for that job.
Existing MaestroQA customers who are happy with their scorecards also keep them: Rippit says rubrics, scorecards and calibration history carry over as-is. If you stay, confirm the integrations and QA workflows you depend on are on Rippit's current roadmap; if they are not, Intryc covers QA, coaching and training for human and AI agents in one platform.
MaestroQA alternatives FAQ
What happened to MaestroQA?
MaestroQA renamed itself Rippit in 2026 and now positions itself as an AI conversation data platform. maestroqa.com redirects to rippit.com, and Rippit says existing MaestroQA scorecards, historical scores and calibration history carry over with nothing to migrate.
Is Rippit still a QA tool?
Partly. Rippit says "QA wasn't retired. Sampled, manual QA was," and QA runs as a configurable agent that scores every conversation with evidence. Rippit now leads with churn, product feedback, chatbot monitoring and coaching, and we did not find MaestroQA's AutoQA, an appeals workflow, coaching-session management or training simulations described on its current pages. MaestroQA's earlier pages documented AutoQA and appeals, so ask Rippit which of those still ship.
What is the best MaestroQA alternative?
For teams that want a dedicated QA platform, Intryc is the strongest fit: it scores every conversation - human and AI - against your own scorecard, runs blind calibration and disputes in one queue, and turns results into AutoCoaching and Simulations. EvaluAgent suits teams that want published per-seat pricing and gamification, and Zendesk QA suits teams that run entirely on Zendesk.
Is Intryc better than MaestroQA?
For running a QA program, Intryc documents more of the QA loop on its public pages: it scores every conversation - human and AI - against your own scorecard, runs blind calibration with a lead-reviewer benchmark, records disputes against human and AI scores in one queue, and turns results into AutoCoaching sessions and Simulations. MaestroQA, now Rippit, is the better fit when the goal is conversation analytics across customer success, product and support.
How much does Rippit cost?
Rippit publishes a free plan with 100 agent runs a month, Starter at $185 a month for 300 runs and Growth at $495 a month for 1,000 runs, with AI credits passed through at cost. Enterprise, which adds SSO, is custom.
Is Rippit worth the price?
Rippit's free plan includes 100 agent runs a month, and paid plans are $185 a month for 300 runs and $495 a month for 1,000 runs, with AI credits at cost. Because one run is one execution of an agent app, a weekly coaching run for 20 agents uses 20 runs, so estimate your volume first. Intryc prices on usage with AutoQA, coaching and Simulations included and no per-agent fees.
What is the cheapest MaestroQA alternative?
Among the alternatives that publish prices, EvaluAgent starts at $35 per user per month and Zendesk lists its QA plus WFM bundle at $50 per agent per month, billed annually. Intryc uses usage-based pricing with no per-agent fees, typically half the cost of per-agent platforms at the same volume.
Can I keep my MaestroQA scorecards if I switch?
Ask Rippit to export your scorecards, criteria and historical scores first, then rebuild the criteria in the new platform and calibrate them on tickets your team already graded. Intryc scorecards support unlimited criteria with weighted, critical and soft modes, so a MaestroQA scorecard can be rebuilt criterion by criterion.
Does Rippit still integrate with Freshdesk, Kustomer, Talkdesk or Five9?
Rippit's current integrations page does not list them; it lists Intercom, Zendesk, Gong, Granola, Decagon and Fireflies as data integrations. Confirm with Rippit before renewing. Intryc integrates with Freshdesk, Freshcaller, Kustomer, Aircall, Twilio, NiCE CXone and Salesforce, among 20+ helpdesk and knowledge-base tools.
Can a MaestroQA alternative score my AI chatbot?
Yes. Intryc imports AI-agent conversations from Ada, Decagon, and Intercom Fin under the bot's own identity, so the chatbot is sampled, scored, and trended as its own agent - on the same scorecard as the humans, or its own. Rippit and EvaluAgent also cover chatbots, so ask each vendor to score a batch of your bot's conversations on your own scorecard and compare the results.
The bottom line
MaestroQA's move to Rippit is a bet on conversation analytics for the whole company. That is useful work - but if your job is running a QA program, the question is whether QA, calibration, disputes, coaching and training stay first-class. Ask every vendor to score a batch of your own tickets on your own scorecard before you sign.
What would your QA program look like if every conversation was scored on your own scorecard and every miss turned into coaching?
Related reading
- Intryc vs MaestroQA - scorecards, calibration and dispute workflows head to head
- Best AI QA software for customer support (2026) - seven platforms compared
- Scorebuddy alternatives - five options compared, with a pilot checklist
- Deel case study